
Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Sub-3 millisecond named entity recognition (NER) inference
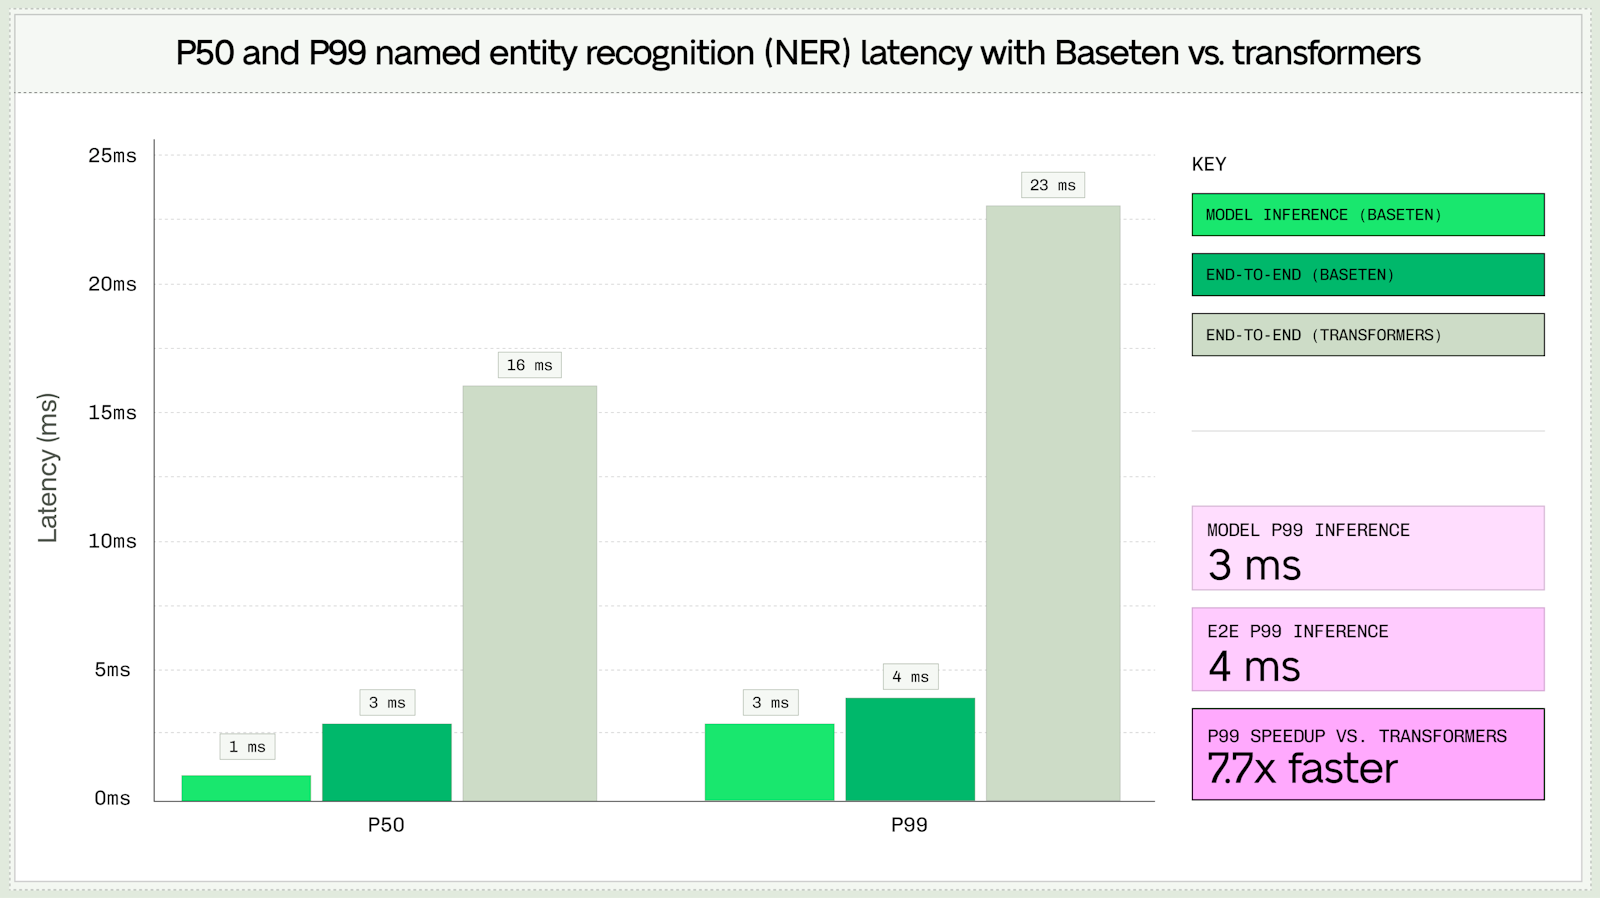
Baseten Embeddings Inference (BEI) now supports NER inference at sub-3 ms client-side and 1 ms server-side, 7x faster than typical solutions.
- Authors
- Last updated
- Originally published


Baseten Embeddings Inference (BEI) started with a simple goal: to make encoder inference so fast that it vanishes into the background of your application.
In service of this goal, we have expanded BEI beyond embeddings to include named entity recognition (NER): a token-classification workload that shows up everywhere in production, from document ingestion and support analytics to compliance pipelines, routing, and retrieval augmentation.
With BEI’s serving path and runtime optimizations, we can run common BERT-class NER models with sub-3 millisecond client-side inference and 1 millisecond server-side inference under realistic production conditions.
This post covers:
What NER models do (and why NER inference has different requirements than embeddings)
What we changed in BEI to make NER inference so fast
How to deploy an NER model with BEI
How to inspect token-level predictions
Optimizing NER inference: NER vs. embeddings
Named entity recognition (NER) models turn free-form text into structured data by identifying character spans that represent entities such as people, organizations, locations, and dates.
Most modern NER models are implemented as token classification:
Tokenize the input text into word pieces (e.g., WordPiece/BPE).
Run an encoder model (often from the BERT family).
Produce a label distribution for every token (e.g., B-PER, I-ORG, O, etc.).
Optionally post-process token labels into entity spans aligned with the original string.
Unlike embedding models (which output one vector per input text), NER returns a prediction per token. That makes the inference compute relatively small compared to the overhead around inference (tokenization, HTTP parsing, JSON serialization, connection behavior, proxying, and framework overhead).
Once the model is fast enough, the real work becomes removing everything else from the hot path.
How we get sub-3 millisecond NER inference
To achieve sub-3 ms NER inference, we focused on removing latency at every layer of the serving stack: the web framework and tokenizer, the proxy, connection handling, and the deployment topology.
Low-overhead serving with Rust
BEI uses a Rust-based web server and tokenizer stack designed for high-throughput encoder workloads. NER benefits even more than embeddings here, because token classification requests can be small enough that a Python web framework’s overhead dominates the end-to-end latency.
By keeping tokenization and request handling in Rust, we minimize per-request overhead and keep CPU utilization predictable under concurrency.
Nginx is configured to stay out of the way
At sub-millisecond inference, “just the proxy” can become the bottleneck. We configure Nginx to reduce overhead on the serving path, minimizing unnecessary buffering and avoiding disk-backed behavior that can introduce latency variance.
The goal is simple: keep the request path memory-backed and lightweight, so the model runtime is what you’re measuring — not incidental IO.
HTTP/2 connection pooling in the Baseten Performance Client
If you benchmark without connection reuse, you’re mostly measuring TLS handshakes, socket setup, and request lifecycle overhead. That’s not what production looks like, and it’s especially misleading when the model itself is extremely fast.
Our Performance Client uses HTTP/2 connection pooling, so repeated requests reuse connections, and your latency reflects inference + minimal request handling rather than repeated setup costs.
Geographical co-location
If you’re calling your NER pipeline as part of a larger processing pipeline, e.g., for anonymization or query understanding, running it in the same physical datacenter can help reduce latency.
Baseten has products like Chains that allow co-location of Baseten deployments.
Calling /predict_tokens vs /hello_world in FastAPI
A helpful mental model:
A minimal FastAPI route like
/hello_worldis effectively a benchmark of framework overhead.A Python-served NER endpoint often adds tokenization, model runtime, and serialization on top of that.
BEI’s
/predict_tokensis designed to keep overhead low enough that token classification can run at the speed the hardware allows.
When you’re chasing sub-millisecond inference, these differences matter: at that point, even “small” overhead (routing layers, connection setup, JSON parsing/encoding) can dominate end-to-end latency.
How to deploy an NER model with BEI
Below is an example configuration for deploying a BERT-family NER model checkpoint via BEI on an L4 GPU. It sets BEI’s default route to /predict_tokens, which returns token-level predictions.
model_metadata:
  example_model_input:
    inputs:
      - - Apple is looking at buying U.K. startup for $1 billion
      - - John works at Google in Mountain View, California
    raw_scores: true
    truncate: true
    truncation_direction: Right
model_name: BEI-Bert-ner-bert-base-ner-uncased-truss-example
python_version: py39
resources:
  accelerator: L4
  cpu: "1"
  memory: 10Gi
  use_gpu: true
trt_llm:
  build:
    base_model: encoder_bert
    checkpoint_repository:
      repo: baseten-admin/bert-base-ner-uncased
      revision: main
      source: HF
    max_num_tokens: 16384
  runtime:
    webserver_default_route: /predict_tokens
A few notes:
base_model: encoder_bertselects the encoder runtime path suitable for token classification.webserver_default_route: /predict_tokensmakes the model behave like a dedicated token prediction endpoint.raw_scores: truereturns per-label probabilities per token (useful if you want to apply confidence thresholds or custom decoding).
Getting NER predictions from BEI
BEI returns token-level predictions from /predict_tokens. The response includes one entry per token and (when enabled) a per-label probability distribution.
Here’s a minimal BEI-only script that:
Sends a list of texts
Prints the top 1 label + score per token
Optionally prints the top scores per token when
raw_scores = true
"""
BEI-only NER predictions
- Calls /predict_tokens with a list of texts
- Prints per-token top-1 label + score
"""

import json
from baseten_performance_client import PerformanceClient

client = PerformanceClient(
    base_url="https://model-<model-id>.api.baseten.co/environments/production/sync"
)

def bei_predict(texts: list[str], raw_scores: bool):
    resp = client.batch_post(
        "/predict_tokens",
        payloads=[{"inputs": [[text] for text in texts], "raw_scores": raw_scores}],
        aggregation_strategy="max"
    )
    return resp.data[0], resp.total_time


def print_predictions(bei_data, raw_scores: bool):
    if not (isinstance(bei_data, list) and len(bei_data) > 0):
        raise ValueError(f"Unexpected BEI response format: {type(bei_data)}: {bei_data}")

    per_text = bei_data[0]
    if not isinstance(per_text, list):
        raise ValueError(f"Unexpected per_text type: {type(per_text)}: {per_text}")

    for text_idx, token_preds in enumerate(per_text, start=1):
        print(f"\n{'=' * 80}")
        print(f"Input {text_idx}")
        print(f"{'=' * 80}")

        if not isinstance(token_preds, list):
            raise ValueError(f"Unexpected token_preds type: {type(token_preds)}: {token_preds}")

        print(f"\n{'Token':<20} {'Label':<20} {'Score':<10}")
        print("-" * 55)

        for token_pred in token_preds:
            tok = token_pred.get("token")

            if "results" in token_pred and isinstance(token_pred["results"], dict):
                best_label, best_score = max(
                    token_pred["results"].items(),
                    key=lambda x: x[1]
                )
                print(f"{tok:<20} {best_label:<20} {float(best_score):<10.4f}")

                if raw_scores:
                    topk = sorted(
                        token_pred["results"].items(),
                        key=lambda x: x[1],
                        reverse=True
                    )[:5]
                    topk_str = ", ".join(
                        [f"{lbl}:{float(scr):.4f}" for lbl, scr in topk]
                    )
                    print(f"{'':<20} {'top5':<20} {topk_str}")

            elif "label" in token_pred and "score" in token_pred:
                print(
                    f"{tok:<20} "
                    f"{str(token_pred['label']):<20} "
                    f"{float(token_pred['score']):<10.4f}"
                )

            else:
                raise ValueError(
                    f"Unexpected token prediction format:\n"
                    f"{json.dumps(token_pred, indent=2)}"
                )


if __name__ == "__main__":
    test_texts = [
        "Apple is looking at buying U.K. startup for $1 billion",
        "John works at Google in Mountain View, California",
        "The Eiffel Tower is in Paris, France",
    ]

    bei_data, _ = bei_predict(test_texts, raw_scores=False)
    print_predictions(bei_data, raw_scores=False)
Drop BEI into your existing NER pipeline
If you’re already using NER in production, switching the inference layer is often the easiest way to make the pipeline faster (and cheaper) without changing your models or your application logic. BEI NER is designed for exactly that: a low-overhead serving path for encoder workloads where “everything else” can dominate latency.
If you want to deploy a specific NER checkpoint (or a token classifier for PII detection, moderation, or routing), you can use the same BEI workflow — point BEI at your checkpoint, expose /predict_tokens, and scale it like any other Baseten deployment. If you have any questions, reach out or check out our docs; we’re happy to help!