
Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Nemotron 3 Diarization
NVIDIA/Nemotron 3 Diarization
An open-weight speaker diarization model that identifies who spoke when in real time, with accurate, low-latency tracking—even during overlapping speech.
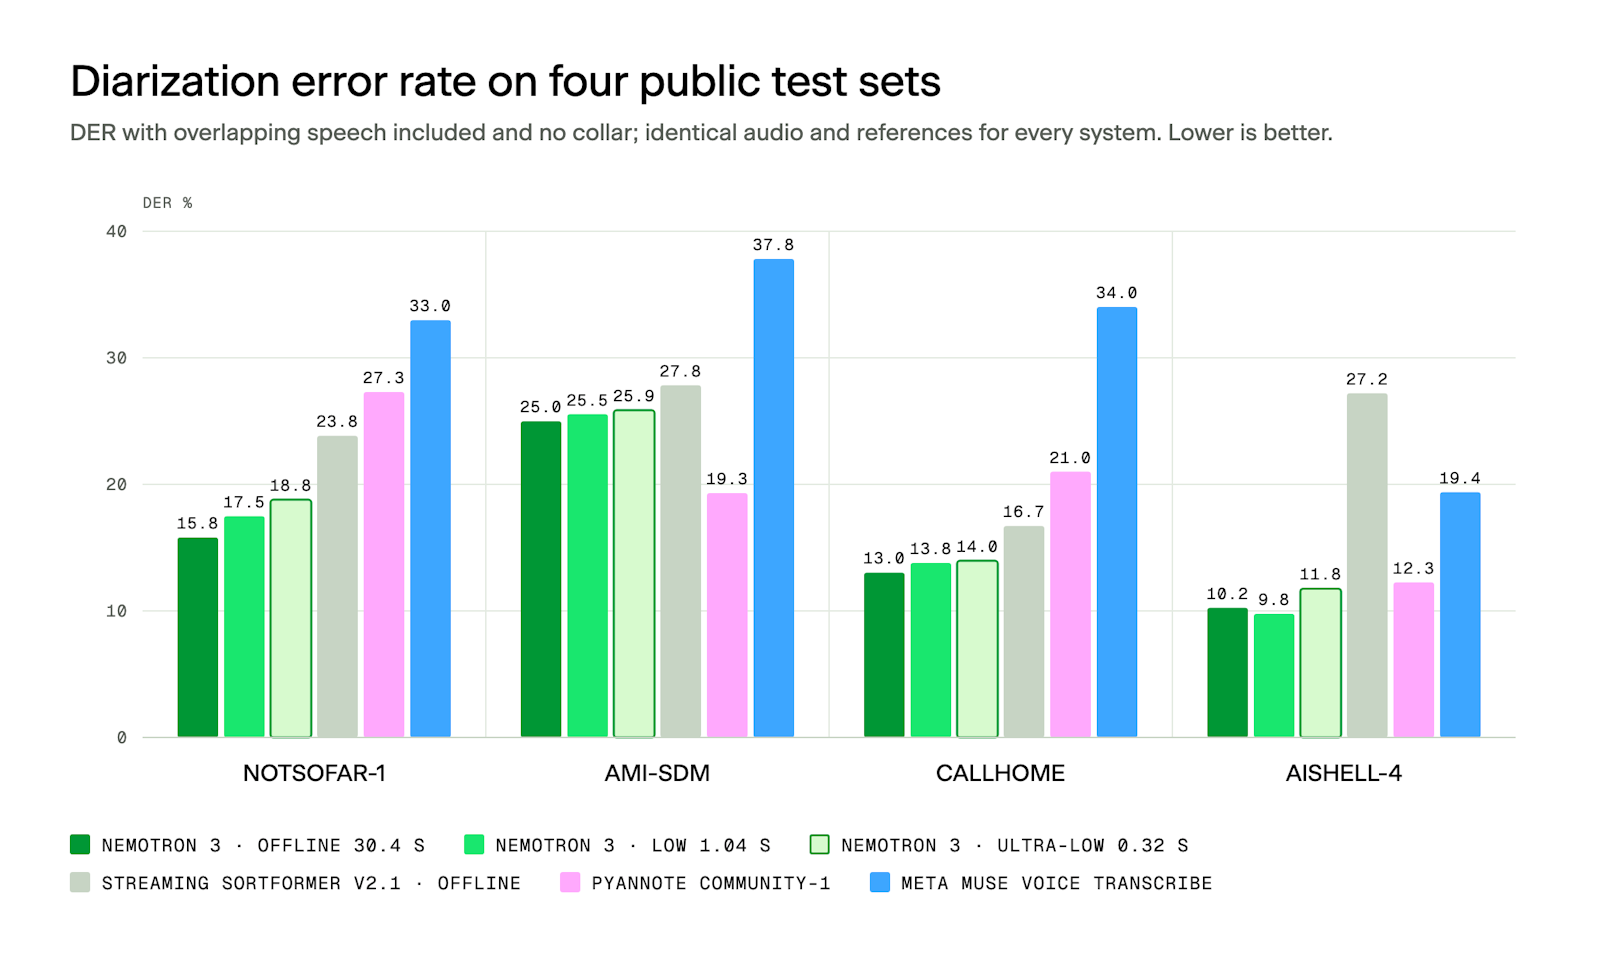
NVIDIA Nemotron 3 Diarization answers "who spoke when" in real-world audio: up to eight speakers, labels ordered by first arrival, and a single checkpoint that runs at any of several algorithmic latencies, from an 0.32-second buffer for live agents to a 30-second buffer for recordings. It is the successor to Streaming Sortformer v2.1 and is released under the OpenMDW 1.1 license for commercial use.
Using the model
On Baseten, Nemotron 3 Diarization is available as three presets, each tuned for a different way of consuming it. Every preset runs on one NVIDIA RTX PRO 6000 and is served with a CUDA-graph engine that we built around NVIDIA's NeMo streaming loop.
Real-Time Diarization
A low-latency WebSocket endpoint for live audio, carrying speaker identity throughout the conversation without re-clustering. A GPU can sustain 500+ concurrent streams at the 1.04-second algorithmic latency profile, and 200 at 0.32 algorithmic latency.
import asyncio, base64, json, os, wave
import websockets  # pip install websockets

KEY = os.environ["BASETEN_API_KEY"]
MODEL = os.environ["BASETEN_MODEL_ID"]
URL = f"wss://model-{MODEL}.api.baseten.co"
URL += "/environments/production/websocket"


async def diarize(path, latency="low"):
    # 16 kHz mono 16-bit WAV
    with wave.open(path, "rb") as f:
        pcm = f.readframes(f.getnframes())
    auth = {"Authorization": f"Bearer {KEY}"}
    async with websockets.connect(
        URL, additional_headers=auth, open_timeout=600
    ) as ws:
        # "low", "ultralow", or "offline"
        await ws.send(json.dumps({"latency": latency}))

        async def send():
            # 100 ms frames at real-time pace
            for i in range(0, len(pcm), 3200):
                b64 = base64.b64encode(pcm[i:i + 3200])
                await ws.send(json.dumps({
                    "type": "input_audio_buffer.append",
                    "audio": b64.decode(),
                }))
                await asyncio.sleep(0.1)
            await ws.send(json.dumps(
                {"type": "input_audio_buffer.commit"}))

        sender = asyncio.create_task(send())
        async for message in ws:
            frame = json.loads(message)
            if frame.get("type") == "error":
                raise RuntimeError(frame["error"])
            # Full turn list each frame: replace, don't append.
            turns = ", ".join(
                f"{t['speaker']} {t['start']:.1f}-{t['end']:.1f}"
                for t in frame["turns"]
            )
            print(f"{frame['processed_s']:6.1f}s  {turns}")
            if frame.get("is_final"):
                break
        await sender

asyncio.run(diarize("meeting.wav"))An HTTP endpoint for recorded audio. Send a file URL or base64 audio, and pick a latency profile per request, get back speaker turns. One RTX-PRO-6000 can process 200 six-minute files per minute.
import os
import requests

model_id = os.environ["BASETEN_MODEL_ID"]
response = requests.post(
    f"https://model-{model_id}.api.baseten.co/environments/production/predict",
    headers={"Authorization": f"Bearer {os.environ['BASETEN_API_KEY']}"},
    json={
        "diarization_input": {
            "audio": {"url": "https://github.com/ggerganov/whisper.cpp/raw/master/samples/jfk.wav"},
            "latency": "offline",
        }
    },
    timeout=300,
)
response.raise_for_status()
for turn in response.json()["turns"]:
    print(f"{turn['speaker']}  {turn['start']:7.2f}  {turn['end']:7.2f}")
Real-Time Diarized Transcription
Nemotron 3 Diarization paired with NVIDIA's multitalker Parakeet 0.6B ASR (more alternative ASR options are in progress!). Send live audio, receive speaker-tagged words with timings, per-speaker partials, and overlap flags. Speaker labels are final on arrival and committed words are never revised. One GPU holds 190 hour-long streams. Please check out our documentation page for a client example.