
Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Fine-tuning Qwen3-TTS for high-quality voice cloning
A guide to fine-tuning Qwen3-TTS for high-quality voice cloning, comparing ICL, speaker-embedding-only, and fine-tuning approaches with a full training recipe.
- Authors
- Last updated
- Originally published

Building expressive speech experiences that capture the mannerisms and nuance of human speech requires richer, more extensive datasets across a wide range of speech scenarios. Models like Qwen3-TTS already ship with a remarkable ability to perform zero-shot voice cloning from a few seconds of audio. But richer cloning capabilities require fine-tuning over a larger corpus of utterance-level examples.
Closed-source providers typically call this "professional voice cloning," as opposed to "instant voice cloning." It requires a larger upfront dataset curation step, including sourcing a voice actor.
We’ve published a modified version of the official published Qwen3-TTS training recipe in our ml-cookbook for creating single-speaker fine-tuned checkpoints on Baseten Training, which can then be easily deployed on Baseten Cloud as a dedicated deployment.
Three approaches to voice cloning: ICL vs. speaker-embedding-only vs. fine-tuning
Qwen3-TTS was designed with strong voice cloning capabilities in mind, but extracting the best quality and performance from the model requires fine-tuning. Qwen3-TTS has two primary instant voice cloning modes: in-context learning (ICL) and speaker-embedding-only.
In-context learning (ICL)
ICL mode tokenizes your reference audio and reference text and includes them as a prefix for every request. This teaches the relationship between reference audio and reference text at inference time, but it costs a considerable prefill overhead (~100s of tokens) for stronger voice conditioning.
ICL mode can also cause speaker inconsistency due to inherent non-determinism in attention and the current prompt being generated. For longer, non-streaming generations, this is often a solid approach, since those cases avoid frequent reconditioning per utterance.
Speaker-embedding-only mode
Speaker-embedding-only mode passes your reference audio through a smaller speaker embedding model (ECAPA-TDNN) that produces a roughly 10-token embedding, added as a prefix before generation. This yields lower time to first audio (TTFA) at the expense of better speaker capture due to the reduced dimensionality of the speaker embedding. However, the smaller speaker embedding means lower prefill overhead, especially at higher concurrency.
Fine-tuning
The goal of fine-tuning is to capture a richer text-audio alignment relationship without the additional overhead of ICL-based cloning. We accomplish this by training on significantly more text-audio pairings via supervised fine-tuning (SFT) and conditioning the model to generate based on an accumulated speaker embedding across a subset of the pairs.
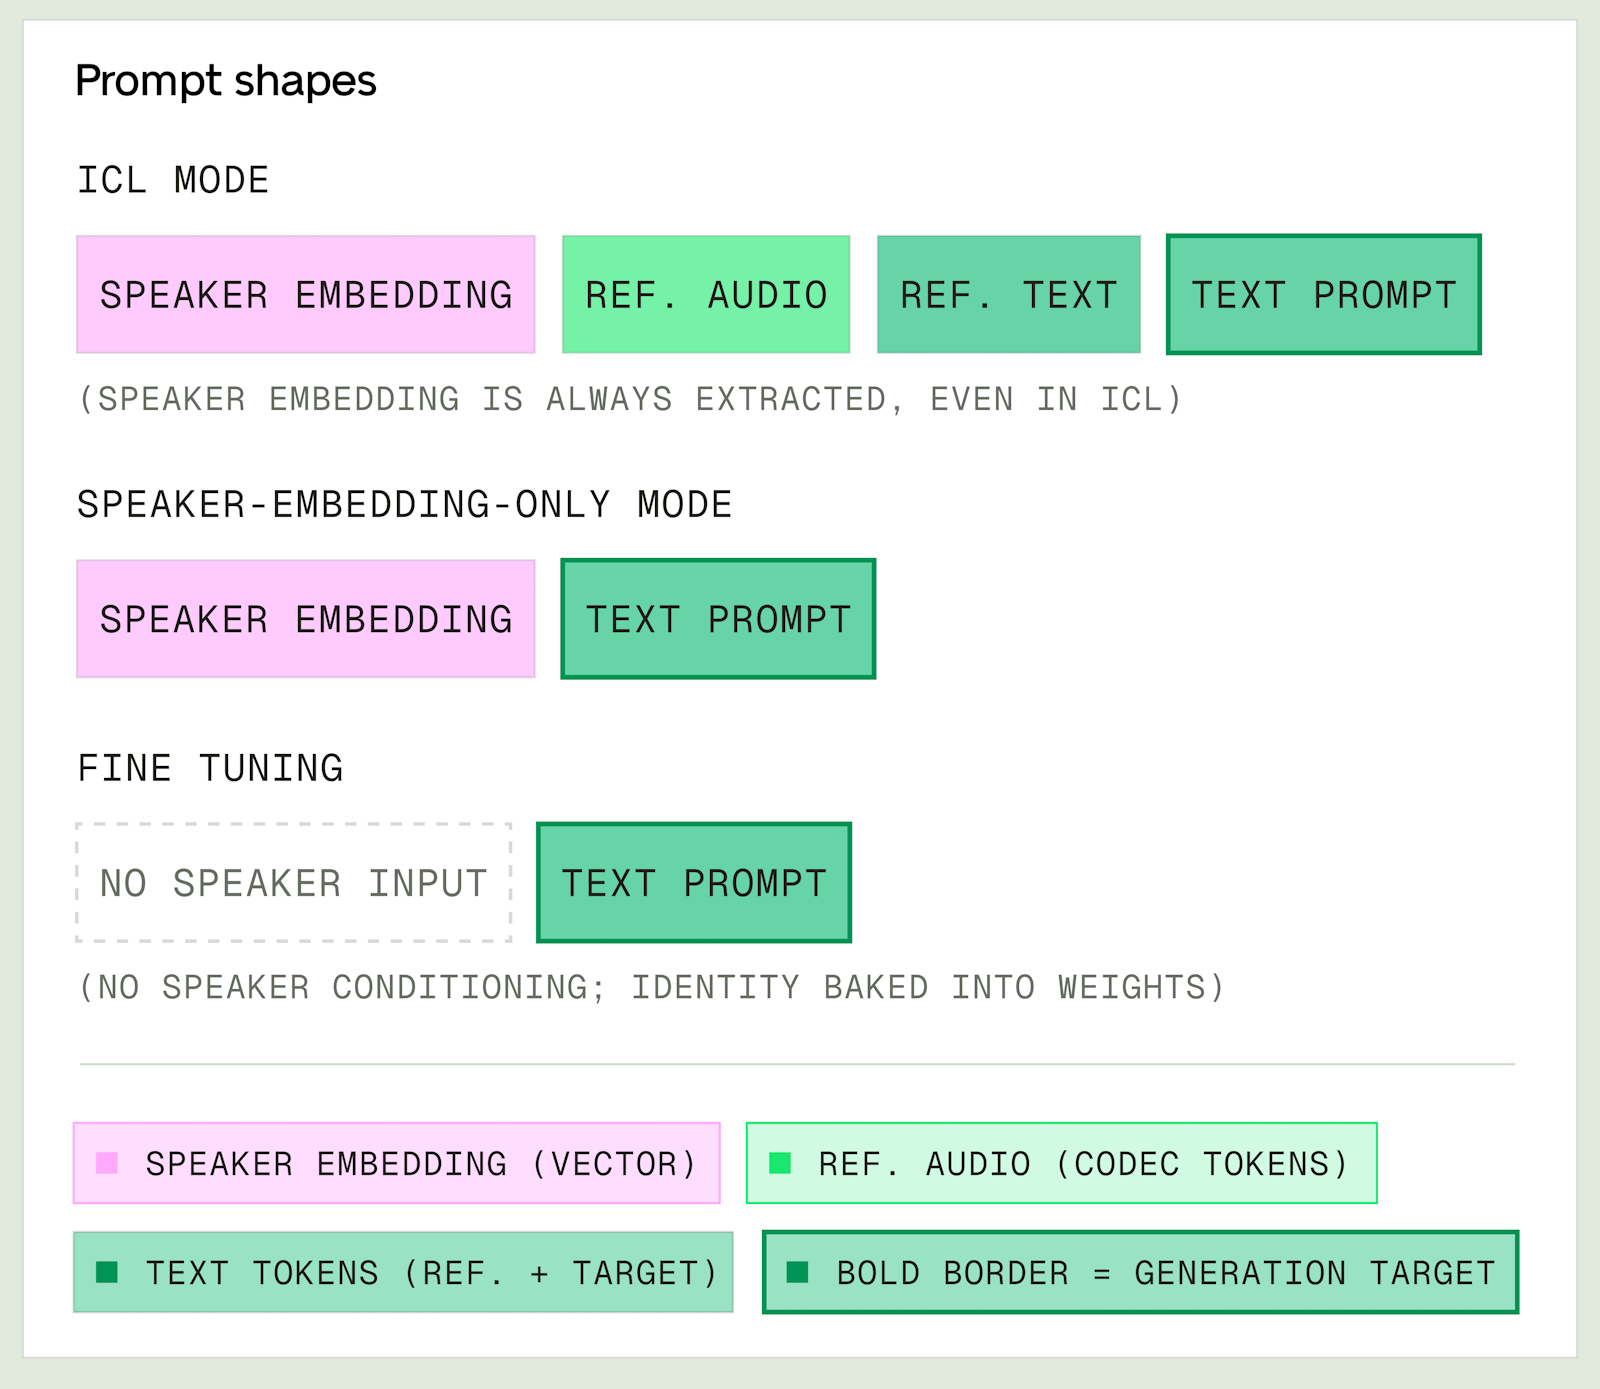
Different prompt constructions based on cloning paradigm
| Approach | Runtime inputs | Pros | Cons |
|---|---|---|---|
| ICL mode (in-context learning) | Reference audio + reference text + text prompt | No training needed; works zero-shot on unseen speakers; captures nuanced vocal characteristics from reference audio | Highest inference cost (longer context, audio tokens to process); quality depends heavily on reference audio quality/length; slower generation |
| Speaker-embedding-only mode | Reference audio + text prompt | Lighter, faster inference (no audio tokens); simpler prompt construction; lower latency | Less expressive/nuanced cloning (embedding alone can't capture everything reference audio conveys); still needs an embedding extraction step upfront |
| Fine-tuning | Text prompt only | Fastest inference (no conditioning overhead); can produce high-fidelity, consistent voices | Requires training a separate model per speaker; not scalable to many/unseen speakers; can't adapt to new speakers without retraining |
Fine-tuning recipe
Step 1: Building the dataset
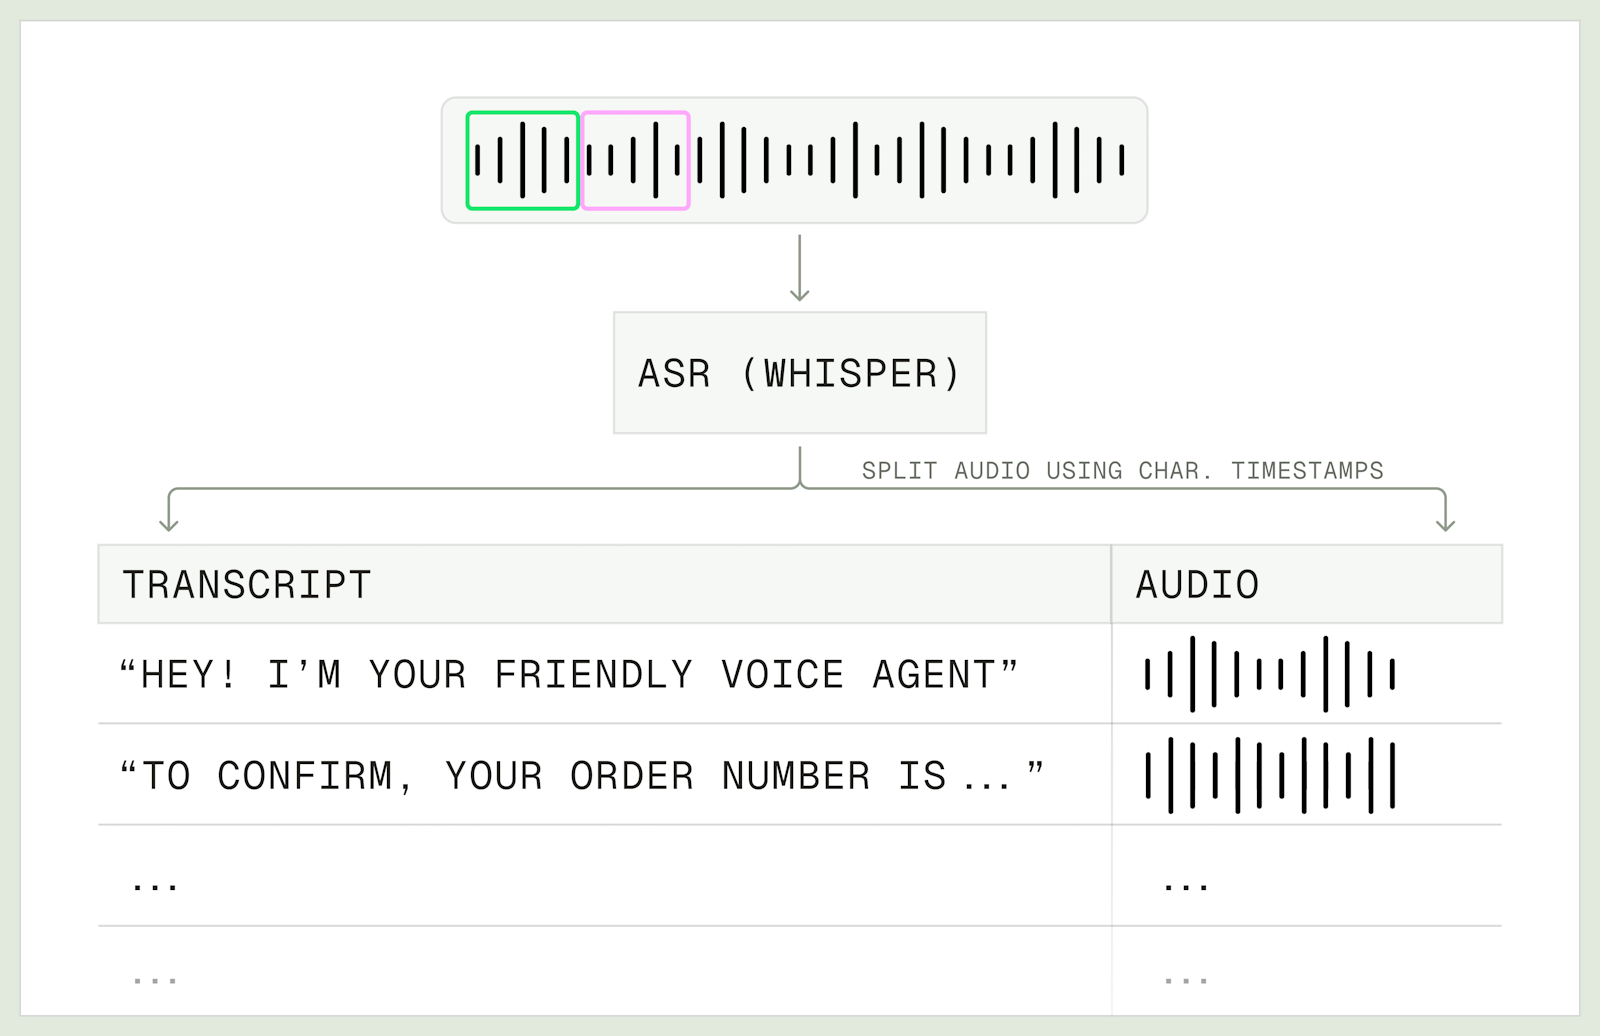
Performing TTS fine-tuning commonly requires a dataset of single-speaker (audio, text) pairs. You can produce these by having the target speaker read a pre-existing transcript, or by generating the dataset with an ASR model in the loop, which only requires audio as input.
Given a long-form audio file, we transcribe it while simultaneously emitting character-level timestamps. These timestamps let us split the transcript and reference audio at closing punctuation, producing utterance-level paired training examples.
We repeat this until the full audio is processed. For the published example, we used the LJ Speech dataset, which contains roughly 24 hours of single-speaker audio (but we fine-tuned on only about 1.5 hours as a more realistic starting point).
Step 2: Training the model
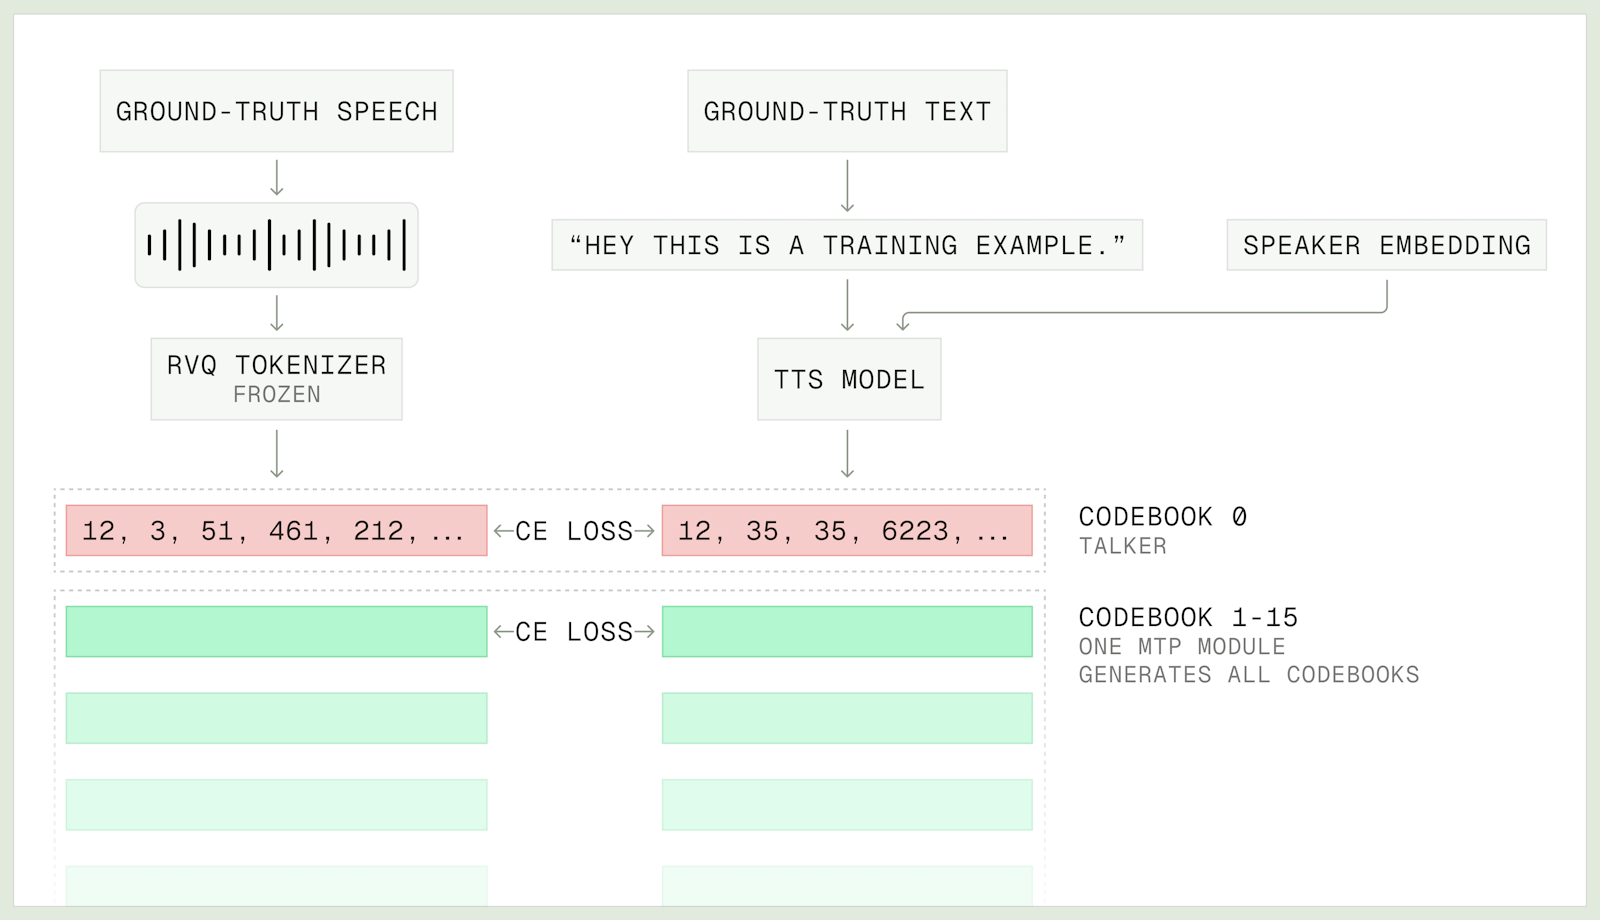
Qwen3-TTS uses a multi-codebook approach to produce audio features that are then decoded into a waveform. Raw waveform audio is too high-rate to model directly; predicting it sample by sample would explode sequence lengths and compute. Instead, vector quantization is applied iteratively to the upstream residuals to produce a compact residual vector-quantized (RVQ) representation: 12 codec frames per second, each spanning 16 codebooks.
As in LLM training, we use cross-entropy loss between the tokenized ground-truth audio and generated speech, split into two components: talker loss and sub-talker loss. Talker loss is the cross-entropy at the first codebook, which carries most of the phonetic and prosodic content. Sub-talker loss aggregates the remaining 15 codebook layers, which capture more fine-grained acoustic detail. The weighting of sub-talker loss relative to talker loss is tunable and an area for further exploration; our recipe used the upstream default of 0.3.
We also updated how the target speaker embedding is derived. Instead of using a single reference clip, we compute it as a centroid: the frozen speaker encoder runs over 64 training clips, and the embeddings are averaged. A single clip is a noisy estimate of voice identity. Per-clip embeddings of the same speaker typically agree at roughly 0.7 cosine similarity with each other, but at 0.85+ with their centroid, so the mean across clips is a more stable target. Sensitivity to the selected reference clip is a known issue with zero-shot cloning, and this approach helps address it systematically. The centroid embedding is then baked directly into the fine-tuned checkpoint, eliminating the need for any reference audio processing at inference time.
We extended the published recipe with linear warmup and cosine learning-rate decay. TTS fine-tuning, like other modalities, is sensitive to learning rate. Values above 1e-5 tend to degrade speaker quality on smaller voice datasets, and a flat schedule both overshoots early (while the speaker head is still adapting) and overfits late. Warmup plus cosine decay smooths both ends, helping the model adapt to the target speaker without degrading its pretrained speech capabilities.
Fine-tuning in action
To illustrate the quality difference between zero-shot voice cloning and fine-tuning, we ran the recipe on a slice of the LJ Speech dataset (800 clips, about 1.5 hours) to resemble the data-constrained settings most voice products actually operate in, where collecting even a few hours of clean, single-speaker audio is a considerable effort.
The fine-tuning run took about 1 hour on a single H100 for 8 epochs. The fine-tuned model achieves a TTFA of roughly 130 ms, matching speaker-embedding-only performance and about 16% faster than ICL (roughly 154 ms), which pays a prefill cost to process reference audio at inference time.
Fine-tuning on 1.5 hours of audio didn't materially beat zero-shot on similarity or MOS-style quality. The case for it is operational (no reference audio, stable latency at scale) and perceptual (better expressiveness on prompts where cloning sounds flat), with room to improve as your dataset grows beyond a few hours of speech.
Some examples where fine-tuning had meaningful improvements on perceived naturalness and expressiveness:
And with more emotion:
And more prosody:
How to further improve text-to-speech fine-tuning results
Beyond SFT, there's growing interest in incorporating RL reward signals (DPO, GRPO) into the post-training loop.
Voice has been a difficult domain for automated evals like LLM-as-judge and is often bottlenecked by more extensive human evals. Automated metrics like EmergentTTS and TTSDSv2 aim to correlate strongly with human ratings on the same audio samples. These can further enhance fine-tuning runs, optimizing checkpoints for human preference rather than a naive cross-entropy objective.
We're also seeing growing demand for richer control over pronunciation and emotion. These are typically closed-source API features, and developing techniques to fine-tune them into existing open-source models is a promising research direction.
Fine-tune your own speech models
We have a Qwen3-TTS fine-tuning recipe published in our ml-cookbook, and you can self-deploy it directly on Baseten Training. Checkpoints produced from Baseten Training can also be referenced directly from a Truss config, for a seamless training-to-inference workflow.
If you have any questions or need support fine-tuning your TTS models, reach out to talk to our engineers.