Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Rumble 2 Flash
Reson8/Rumble-2-Flash
State of art multilingual transcription model, with best-in-class performance in noisy environments
From leading transcription provider Reson8, Rumble 2 Flash brings frontier-level transcription performance within a 0.5B parameter size.
Featured highlights:
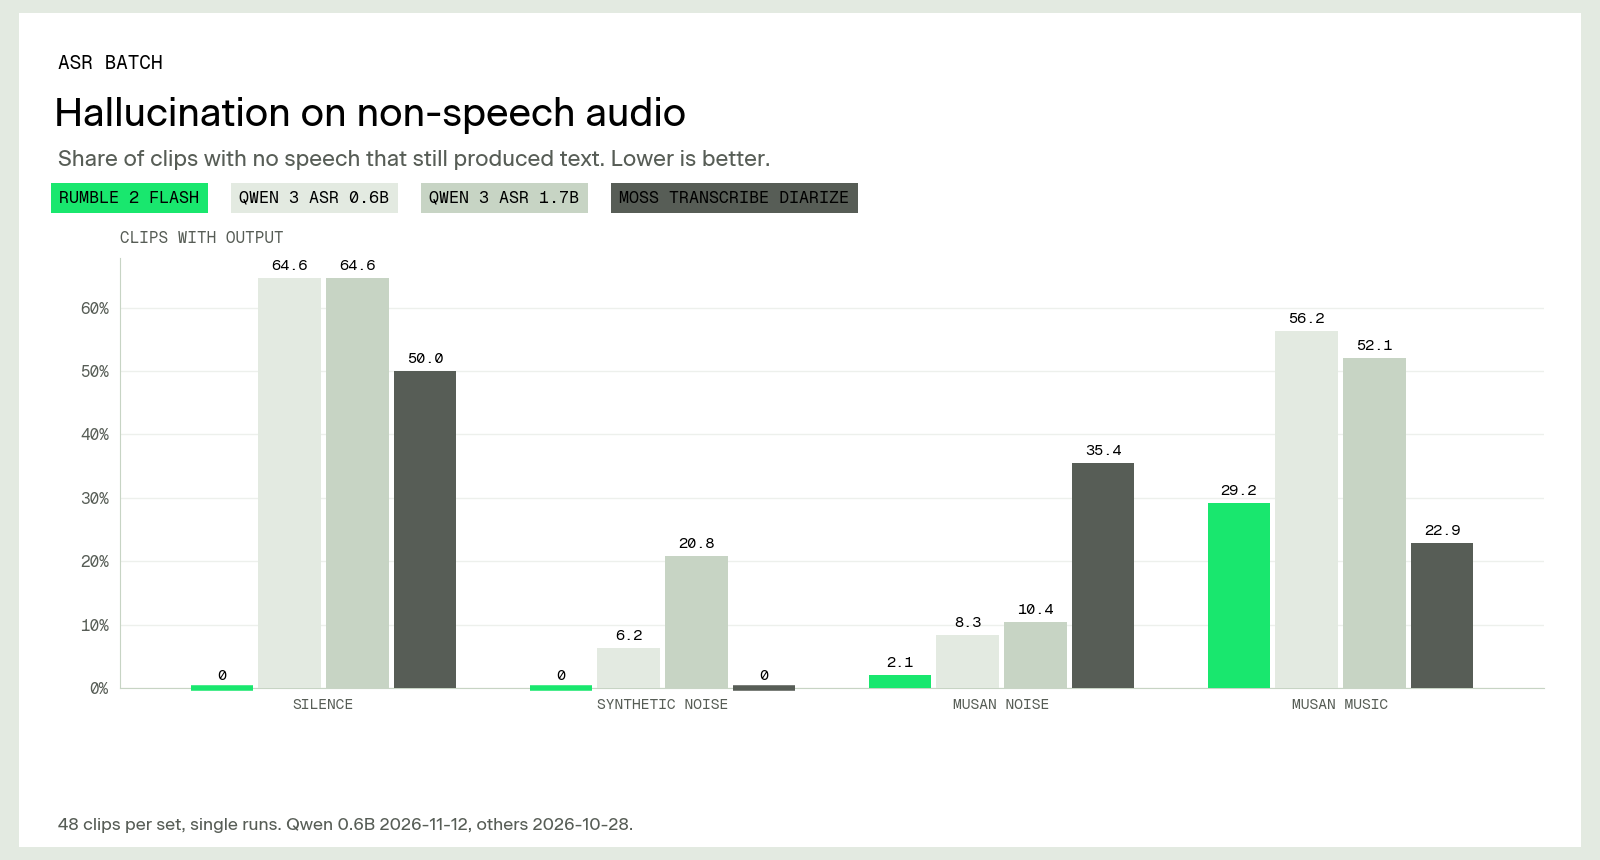
Silence stays silent: Rumble 2 Flash does not hallucinate text on silence, unlike leading open-source models such as Qwen 3 ASR 1.7b, while achieving half the error rate on clips with background music or noise.
Built for Multilingual Use: On European languages, Rumble 2 Flash reaches a FLEURS error rate of only 6.6%,
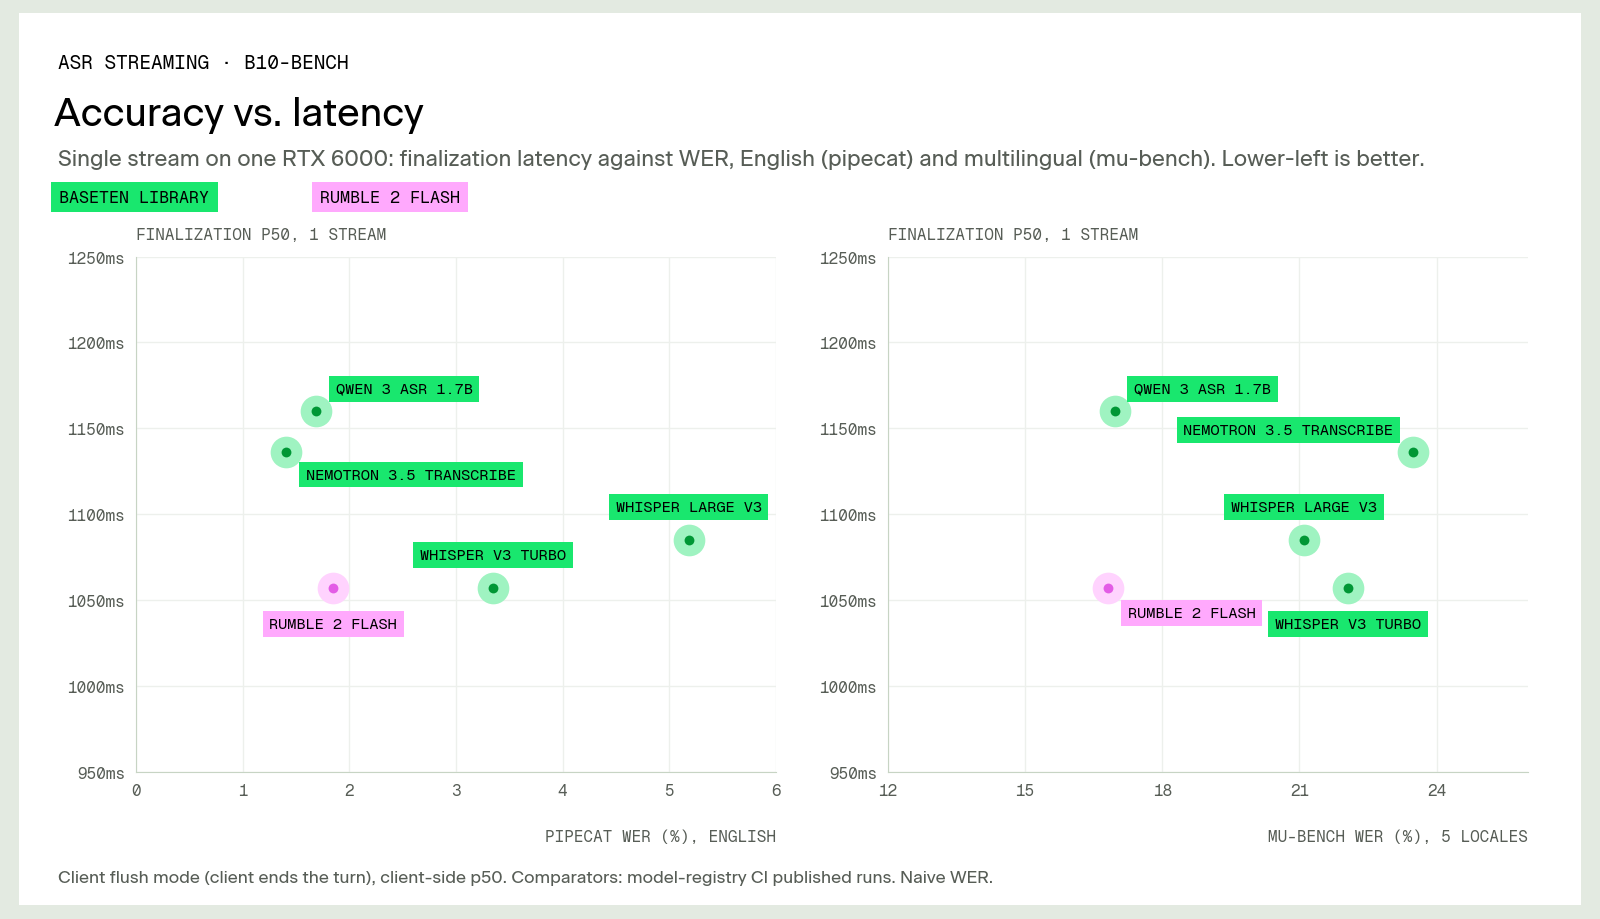
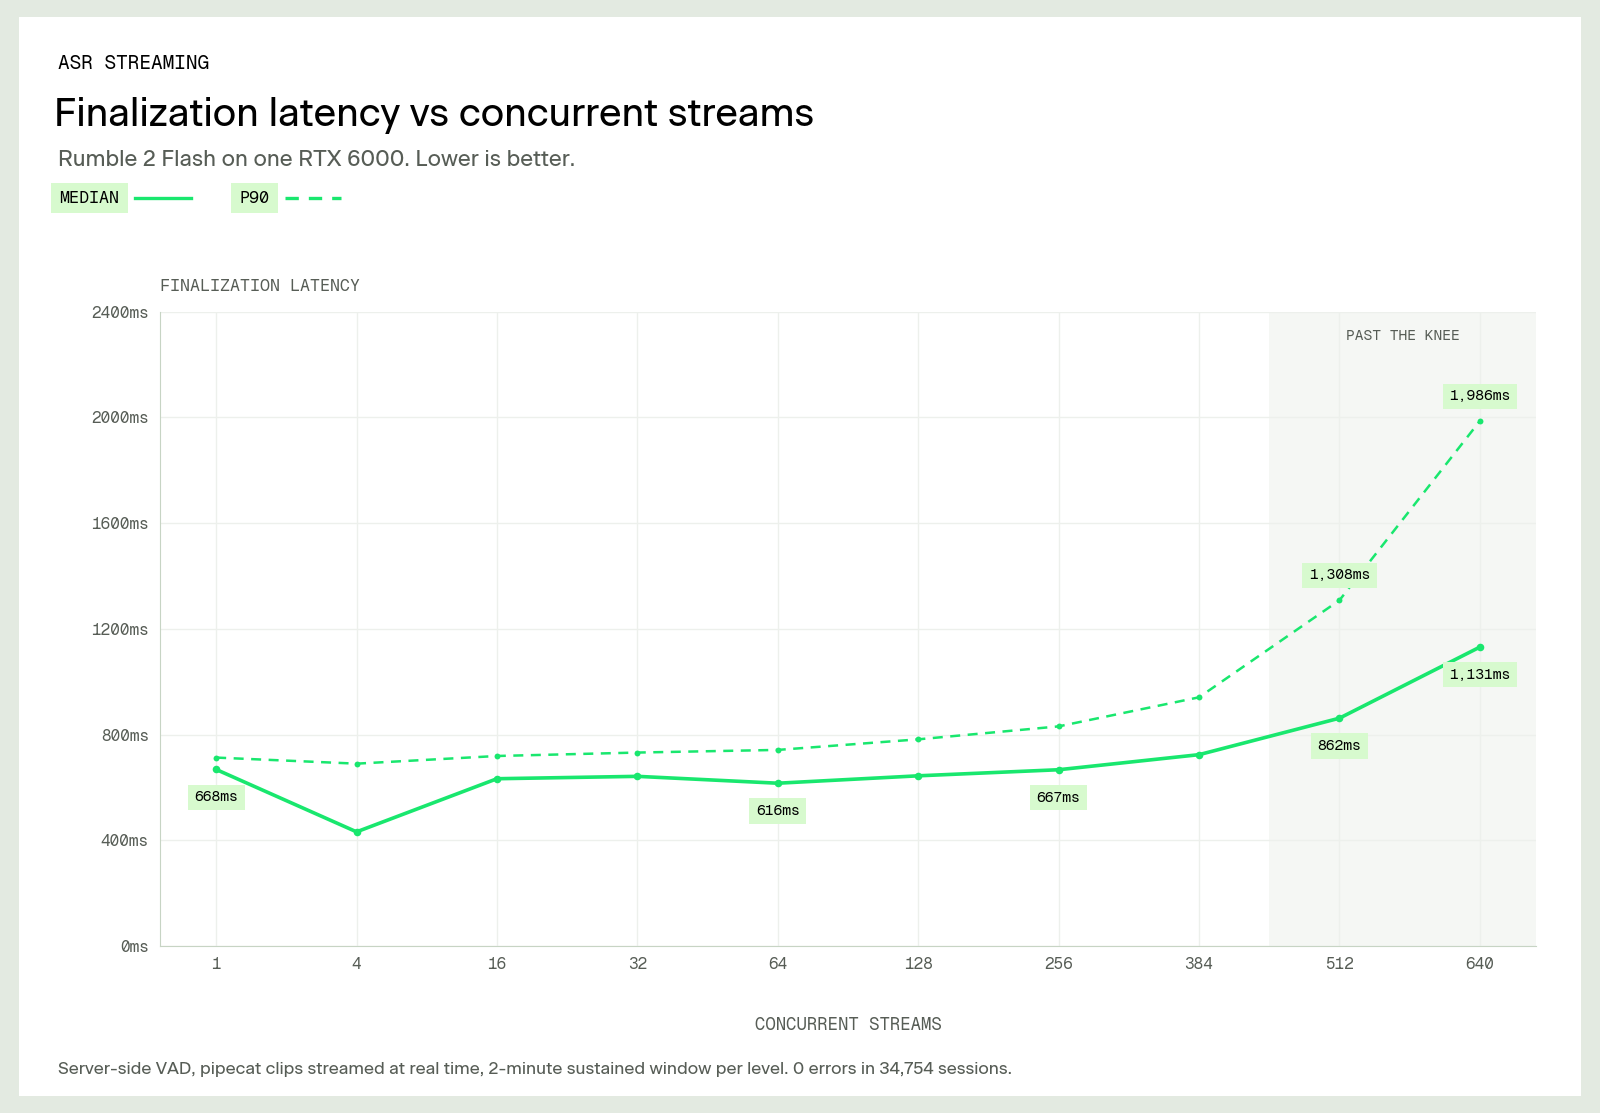
Fast under Load: Even at high concurrency, Rumble 2 Flash can transcribe an hour of audio in under 10 seconds, and maintain up to 100 concurrent streams with sub-second finalization latency.
General Quality:
We measured the performance of Rumble 2 Flash on four datasets of non-speech audio. Compared with the Qwen3-ASR models, it produces dramatically less phantom text from music and background noise, so you get fewer false turns and cleaner transcript.
Batch Endpoint
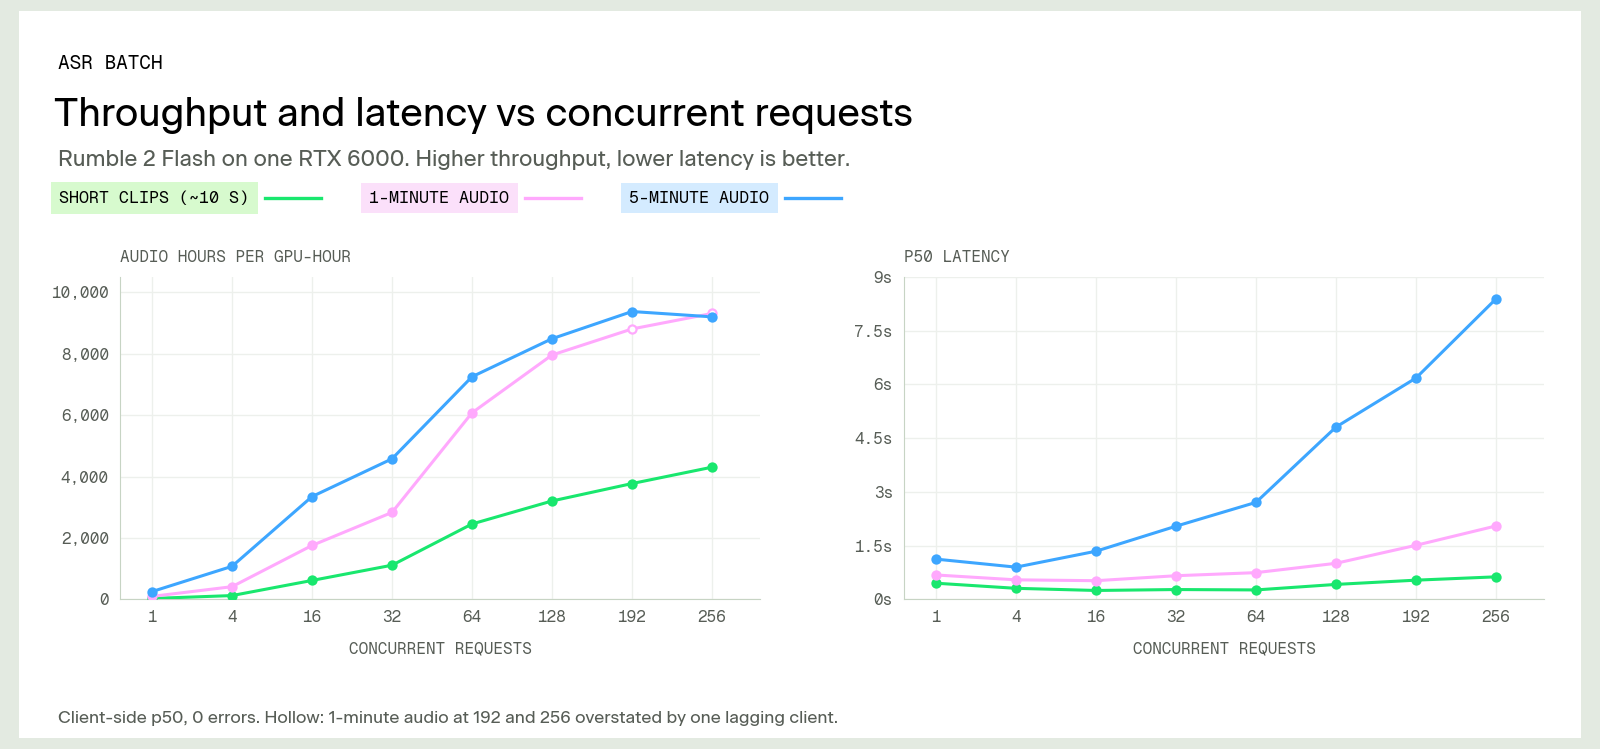
For large transcription jobs, Rumble 2 Flash delivers. Our batch deployment reaches a real-time factor (RTFx) of over 8,000 on one-minute audio on a single RTX PRO 6000 GPU. That's more than two hours of audio transcribed every second, at a fraction of the usual cost when the GPU is kept busy. We serve Rumble 2 Flash using the OpenAI transcription API.
Realtime Endpoint
Rumble 2 Flash is built for live conversation at scale. It keeps p90 latency under one second across up to 400 concurrent streams on a single GPU, enough to power a contact center from one card. Deploy the real-time endpoint in one click from the top right of this page, served behind our own Baseten Realtime Transcription API.
Every workload is different. Our voice AI engineers can help you optimize and customize Rumble 2 Flash for your audio, languages and latency targets. Contact us!