
Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Introducing the Baseten Voice Agent Stack: own and optimize voice agents end-to-end
The Baseten Voice Agent Stack is customizable, low-latency infrastructure for building and running production voice agents at scale.
- Authors
- Published



The Baseten Voice Agent Stack gives teams more control over how they run, customize, and scale voice agents in production. Baseten Realtime Voice, a reference agent built on the stack, achieves sub-second median turn latency across 32 concurrent sessions. Both are now in private preview, join the waitlist here.
Today we’re launching the Baseten Voice Agent Stack and Baseten Realtime Voice to help teams build highly performant, customizable, production-grade voice agent systems they can easily deploy and manage on Baseten.
The Baseten Voice Agent Stack is the infrastructure for running production-grade voice agents on Baseten Dedicated Inference. It runs the orchestrator and every model over a tight in-cluster network for optimal end-to-end latency, scales each component independently, and lets you pick or post-train any model in the pipeline.
Baseten Realtime Voice is an ultra-fast, low-cost voice agent API with frontier-level quality, built on the Baseten Voice Agent Stack. It has ultra-low turn latency, costs ~$0.01 per audio minute, and speaks the OpenAI Realtime protocol, so existing agents can move over with minimal changes.
Both are now in private preview, and you can sign up for our waitlist here.
The Baseten Voice Agent Stack
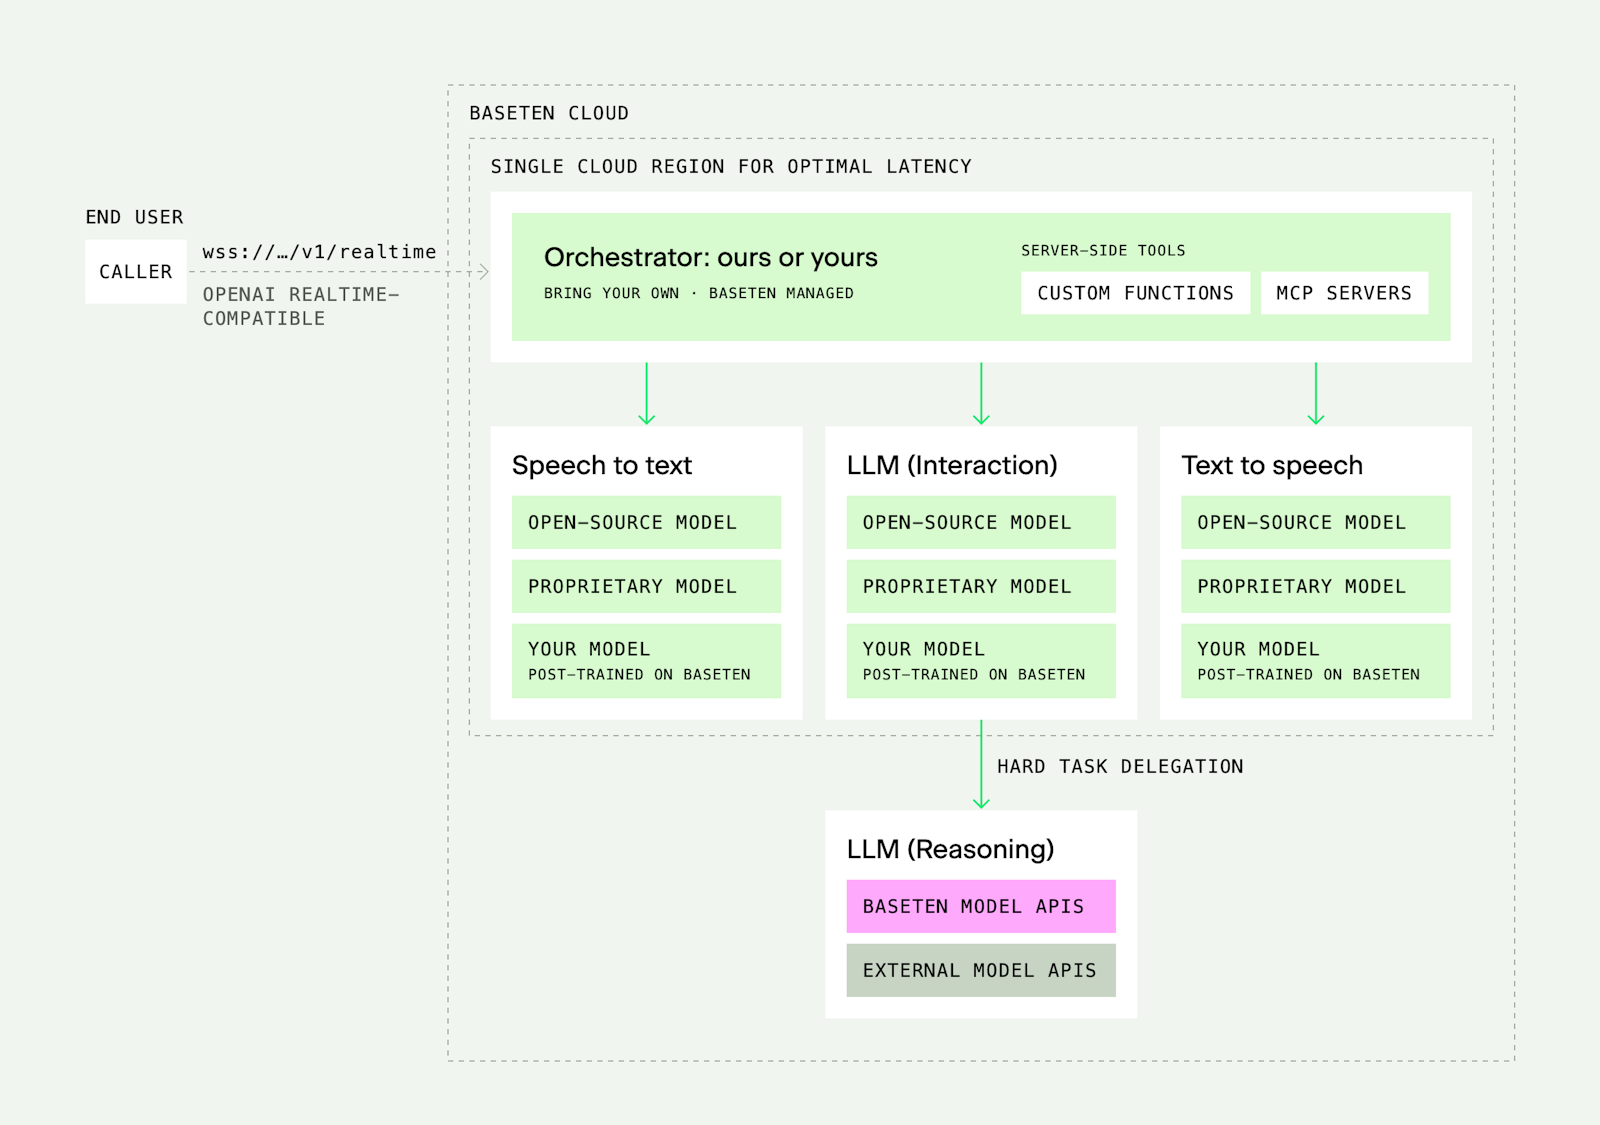
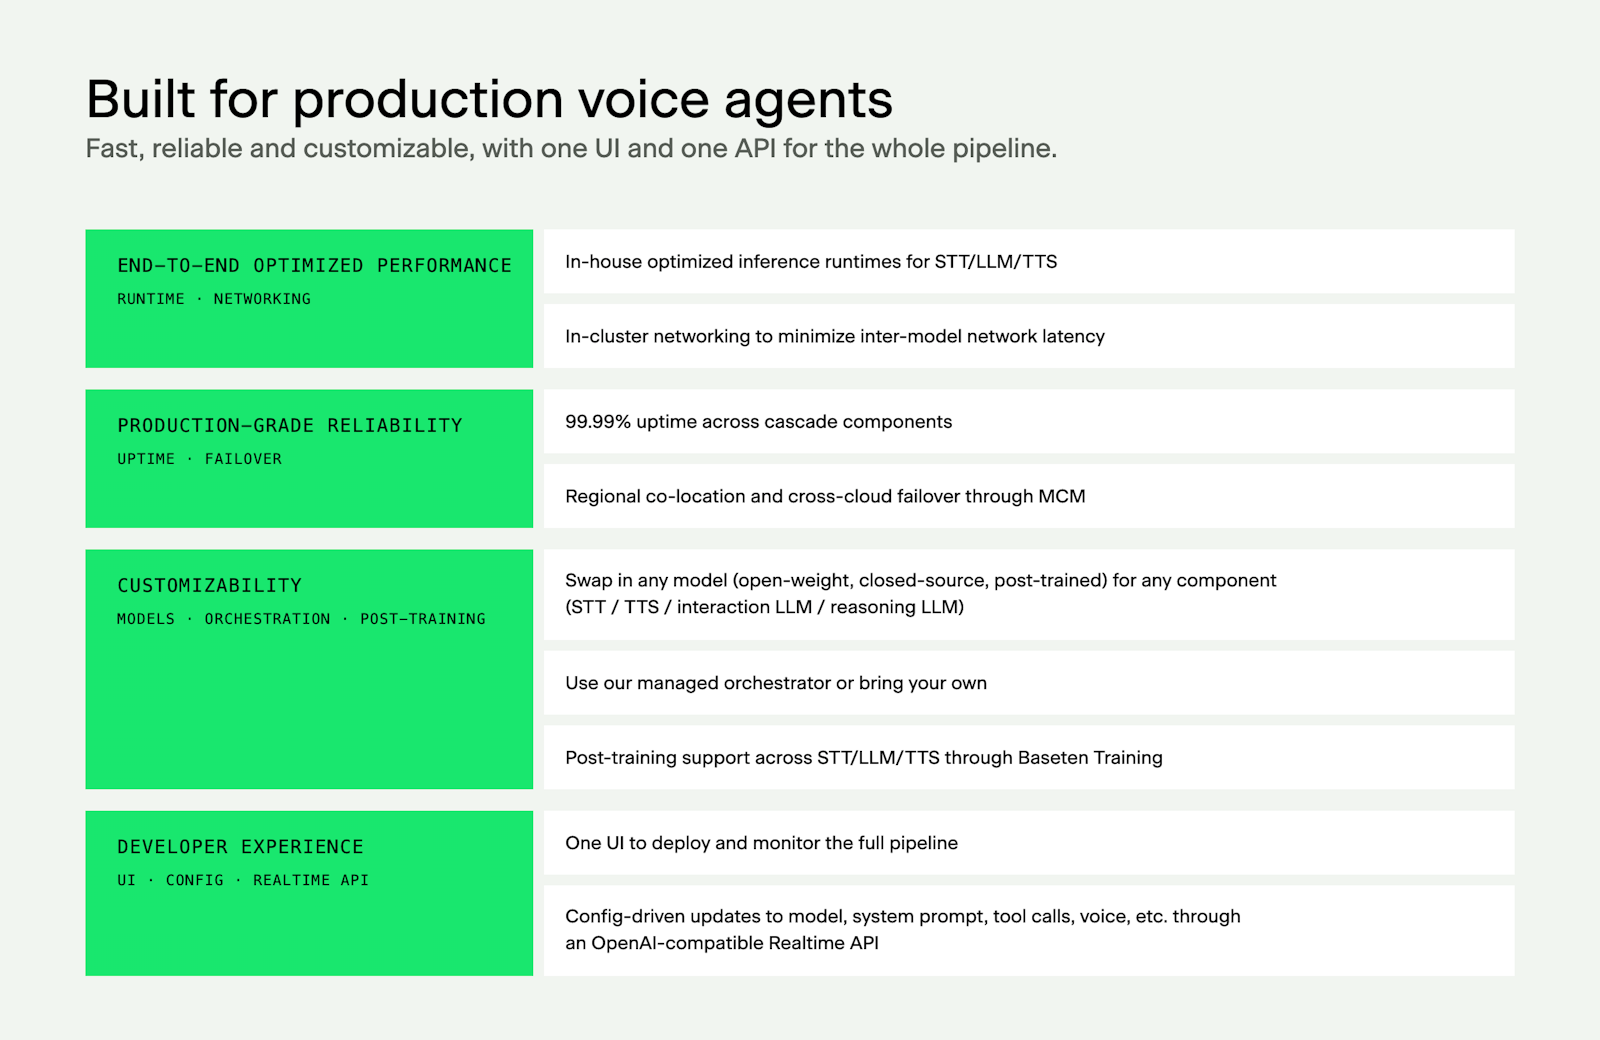
The Baseten Voice Agent Stack brings together all the infrastructure primitives critical to a production-grade voice agent system in one place—from inference runtime optimization and efficient inter-model networking to traffic autoscaling, cross-cloud failover, and model post-training support—so builders can focus on choosing the right models and building their agent’s proprietary business logic.
See the following table for a complete list of feature highlights:
Baseten Realtime Voice: an ultra-fast, super-low-cost voice agent API
To demonstrate what you can achieve with the Baseten Voice Agent Stack, we built Baseten Realtime Voice, a reference voice agent that runs a full cascade of Baseten-optimized open-weight speech models (see footnote 1) alongside a custom Pipecat-based orchestrator. It supports optional delegation, pairing a fast, co-located talker model for conversation with a stronger thinker model for reasoning and tool calls.
On our setup, Baseten Realtime Voice:
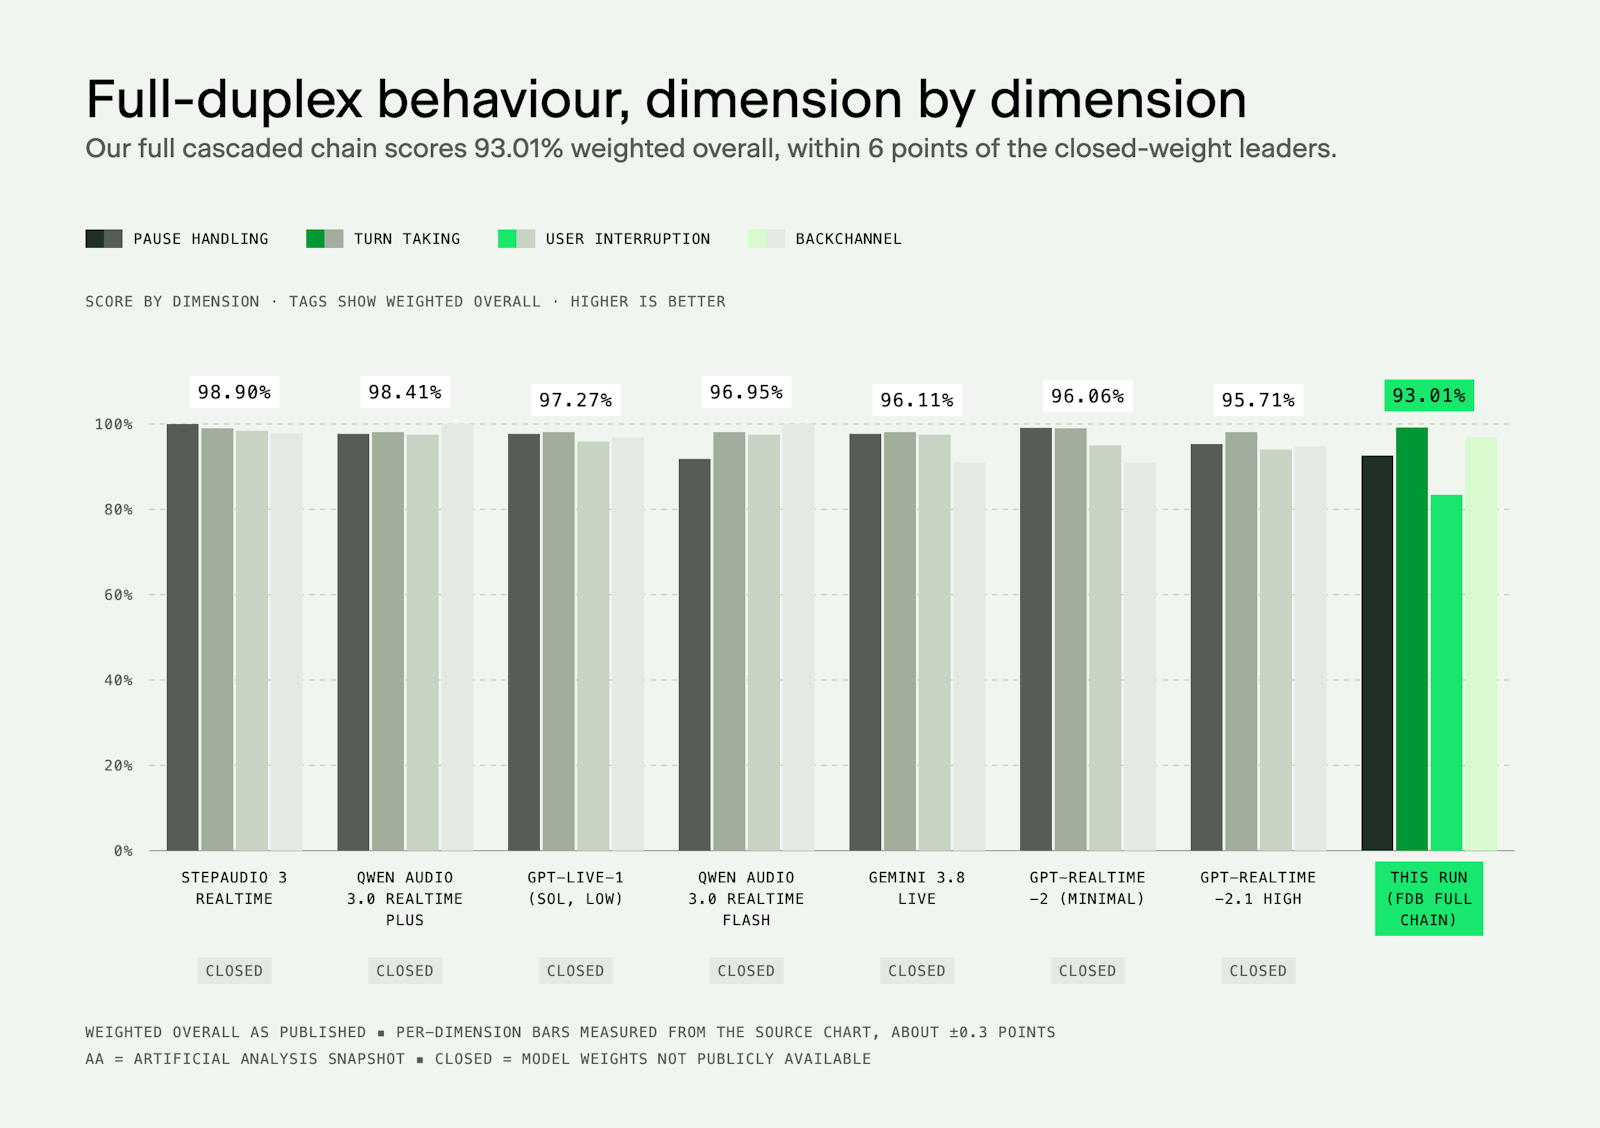
Scores 93% on Full-Duplex-Bench, the highest of any open-source system on Artificial Analysis.
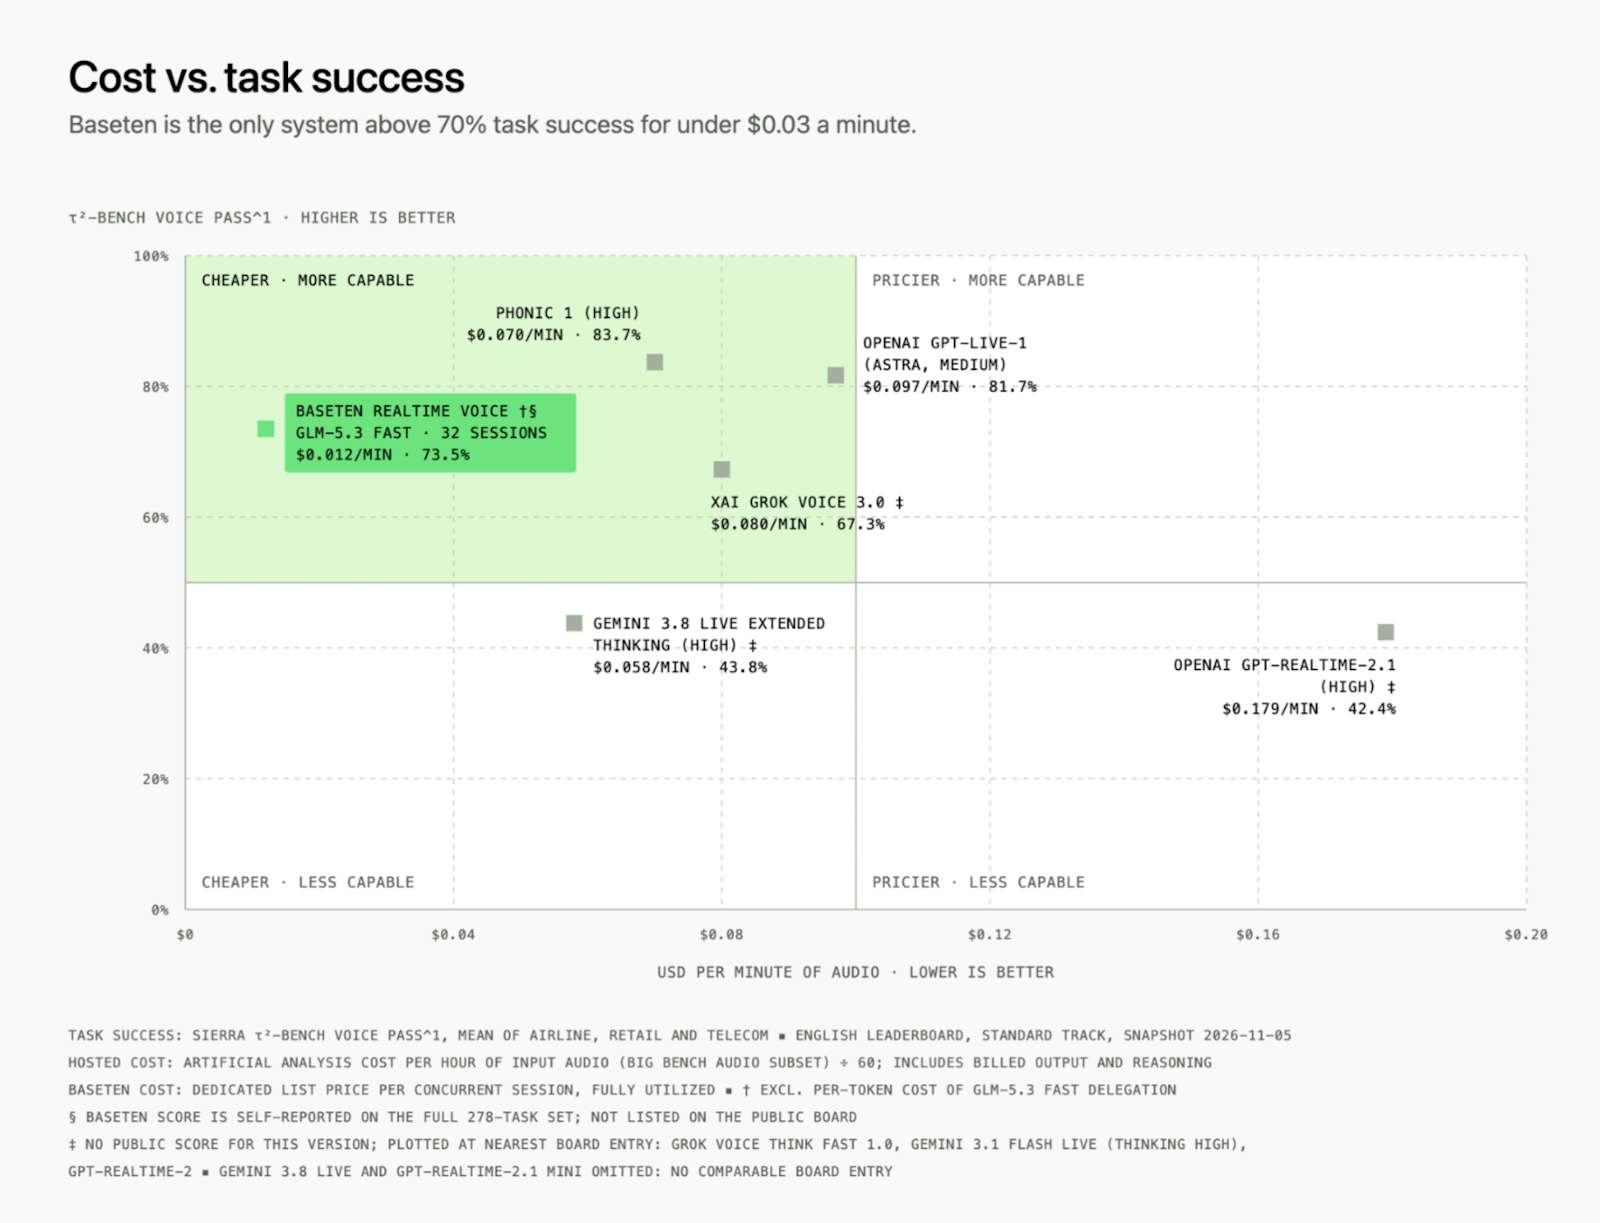
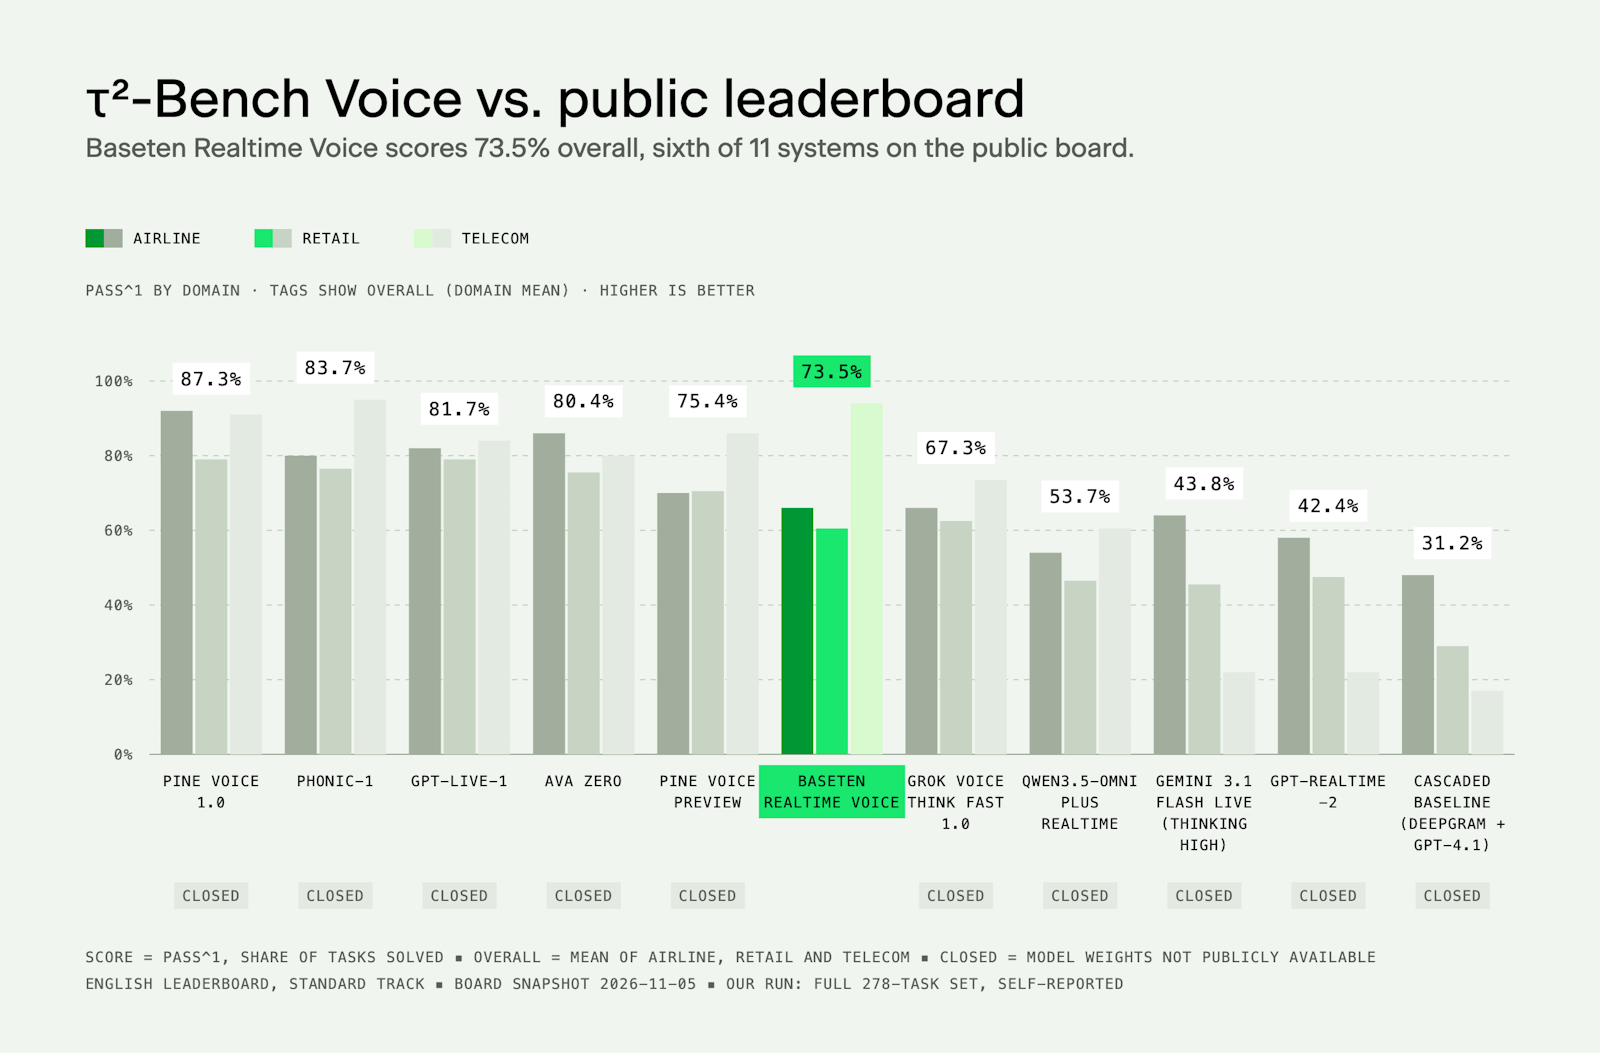
Scores 73.5% on τ²-Bench Voice (see footnote 2), more than double the cascaded baseline.
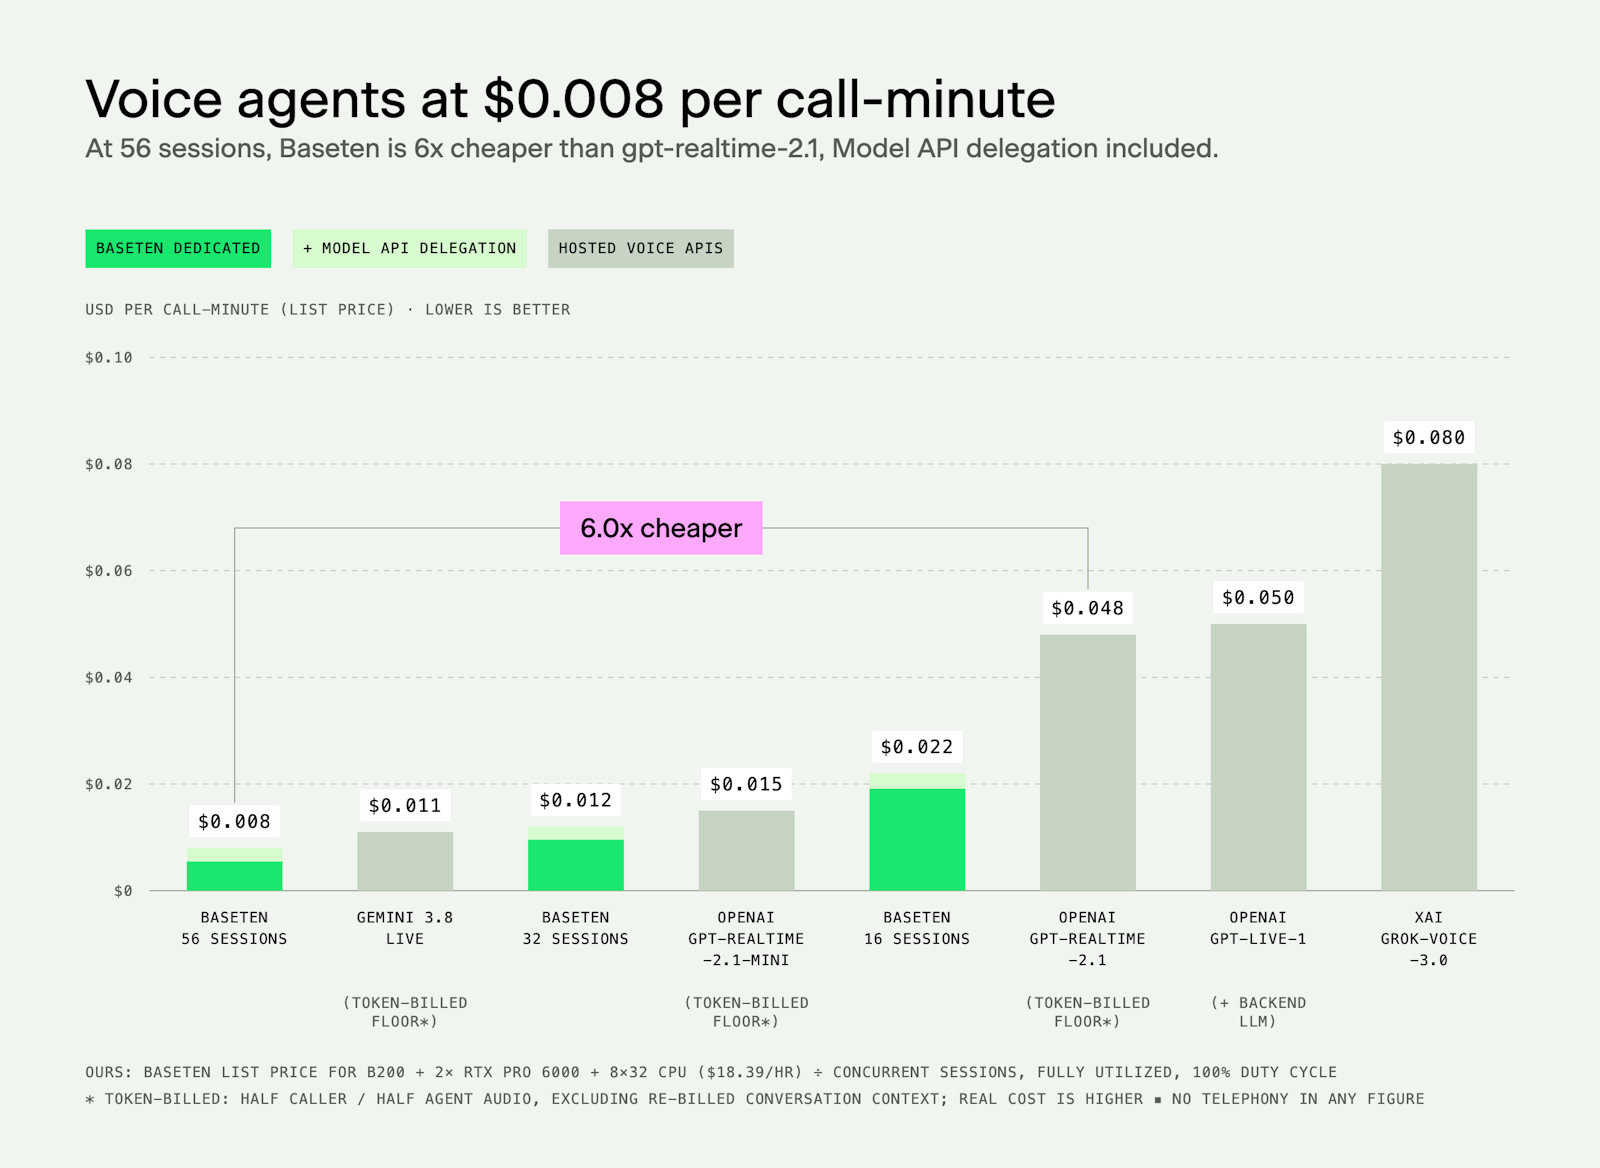
Costs less per minute ($0.012) than every hosted speech-to-speech API we evaluated at 32+ concurrent streams.
Baseten Realtime Voice in action: a voice agent built on the Baseten Voice Agent Stack
A voice agent built on the Baseten Voice Agent Stack can delegate a complex question to a reasoning model and search the web.
Our approach behind Baseten Realtime Voice
Co-located cascade and orchestrator
Co-locating the models isn’t enough on its own. Even with all three components hosted on Baseten, a remote orchestrator still adds 100s of milliseconds of network round trips per turn.
The Baseten Voice Agent Stack runs the orchestrator alongside the models, eliminating those hops.
Full model ownership
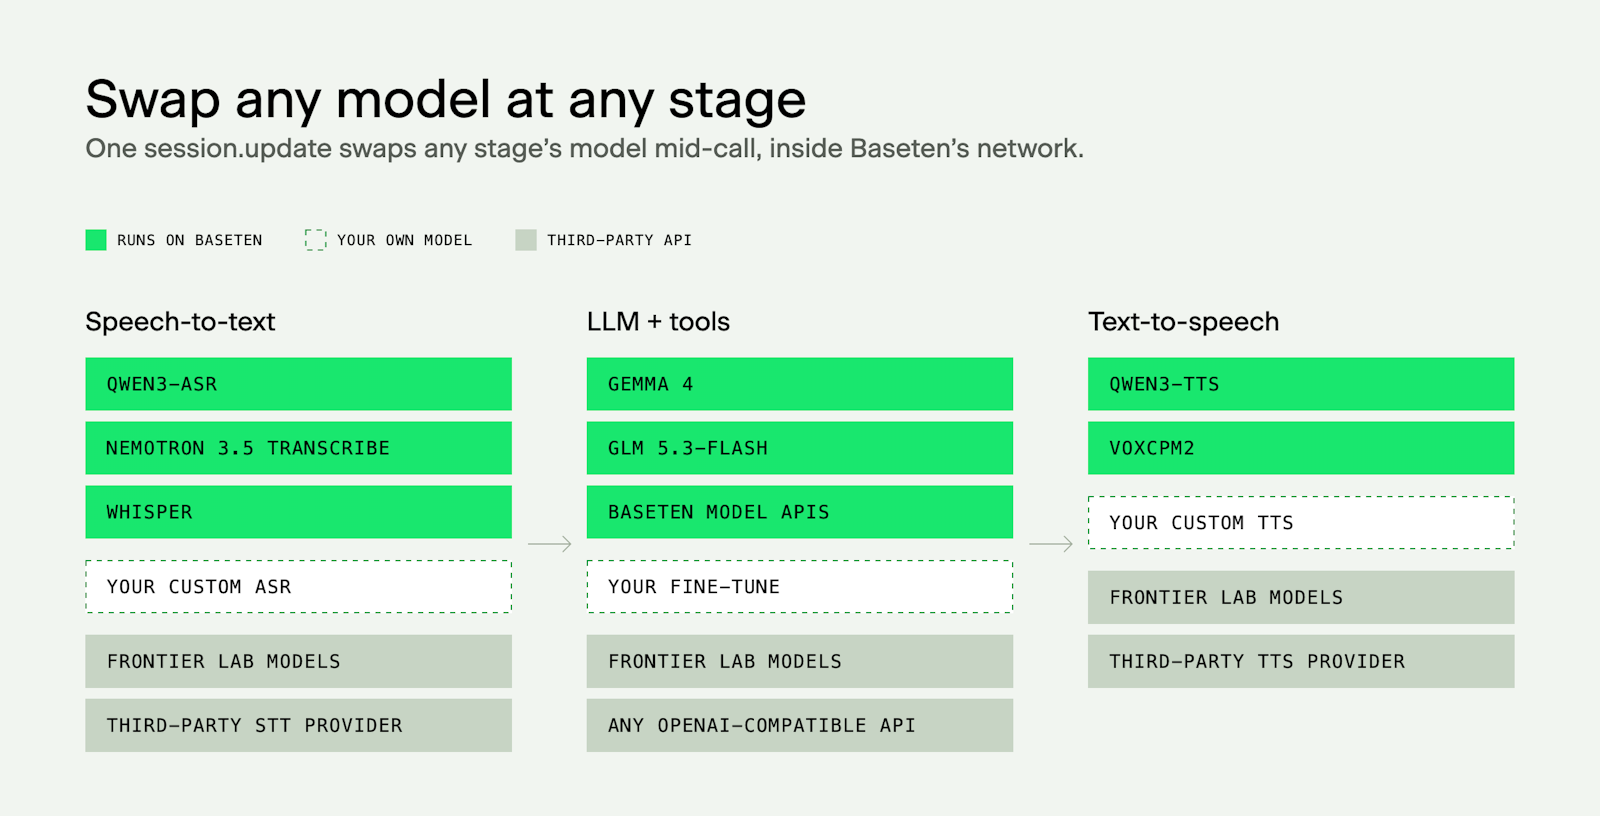
Our voice agent stack is model-agnostic at every stage of the cascade.
When a component is tied to a single vendor, your agent can only improve as fast as that vendor ships new capabilities, or until you migrate to another provider. We take a different approach where we provide the essential orchestration primitives allowing you to bring any STT, LLM, and TTS combination you can already host on Baseten. That includes our best-in-class runtimes for open-weight models and a fast-growing library of Baseten for Model Labs partner models that deliver frontier-lab capabilities at dedicated-deployment unit economics.
The stack also supports popular third-party APIs, so you can mix dedicated and hosted components, allowing you to incrementally move each piece of the cascade onto dedicated infrastructure.
Why post-train voice agents?
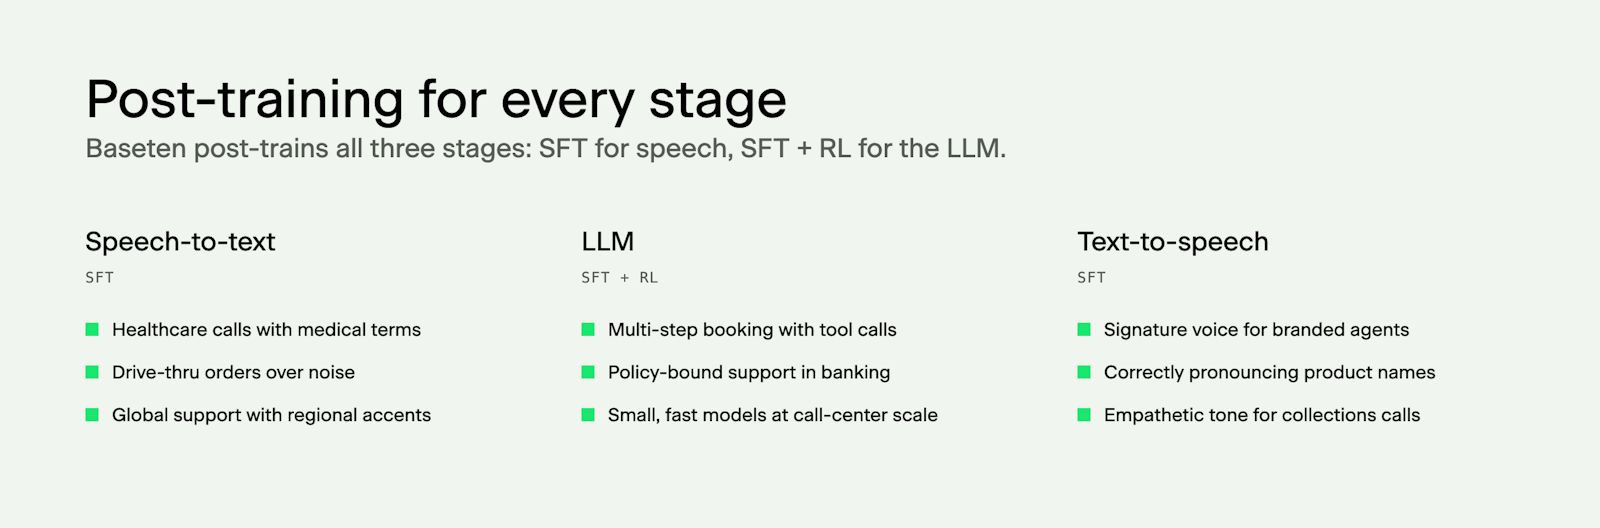
Full model ownership also opens up the possibility of post-training at each level of the cascade. For example, if you are operating an agent in a vertical such as healthcare or financial services, having the ability to post-train your STT model on industry-specific jargon and conversations can vastly differentiate an agent experience from an off-the-shelf offering.
On the LLM front, we’ve seen lots of success post-training LLMs for voice agent companies to improve agent behavior in real-world calling scenarios. Additionally, we’ve built out fine-tuning recipes on Baseten Training for TTS to run supervised fine-tuning with your voice data to improve the expressiveness and naturalness of your agent’s speech.
Delegation for improved reasoning capabilities
Voice agents need to stay responsive even when they’re looking something up or taking an action. With delegation, a co-located talker model handles conversational replies while asynchronously handing off reasoning and capabilities like web search to more powerful external reasoning models.
This allows users to get fast replies from one model while still leveraging reasoning abilities from a stronger external model.
Run tools and MCP server-side to cut tool-calling latency
We support both client-side and server-side tool calling, along with MCP server support, so agents can easily plug into existing knowledge bases and take actions.
Server-side tools execute directly on the orchestrator, which is co-located with the rest of the cascade on Baseten, avoiding additional client round-trips. This further reduces total turn latency and limits client-side implementation overhead, so conversations stay responsive even when the agent is taking actions.
Fast integration with an OpenAI realtime-compatible API
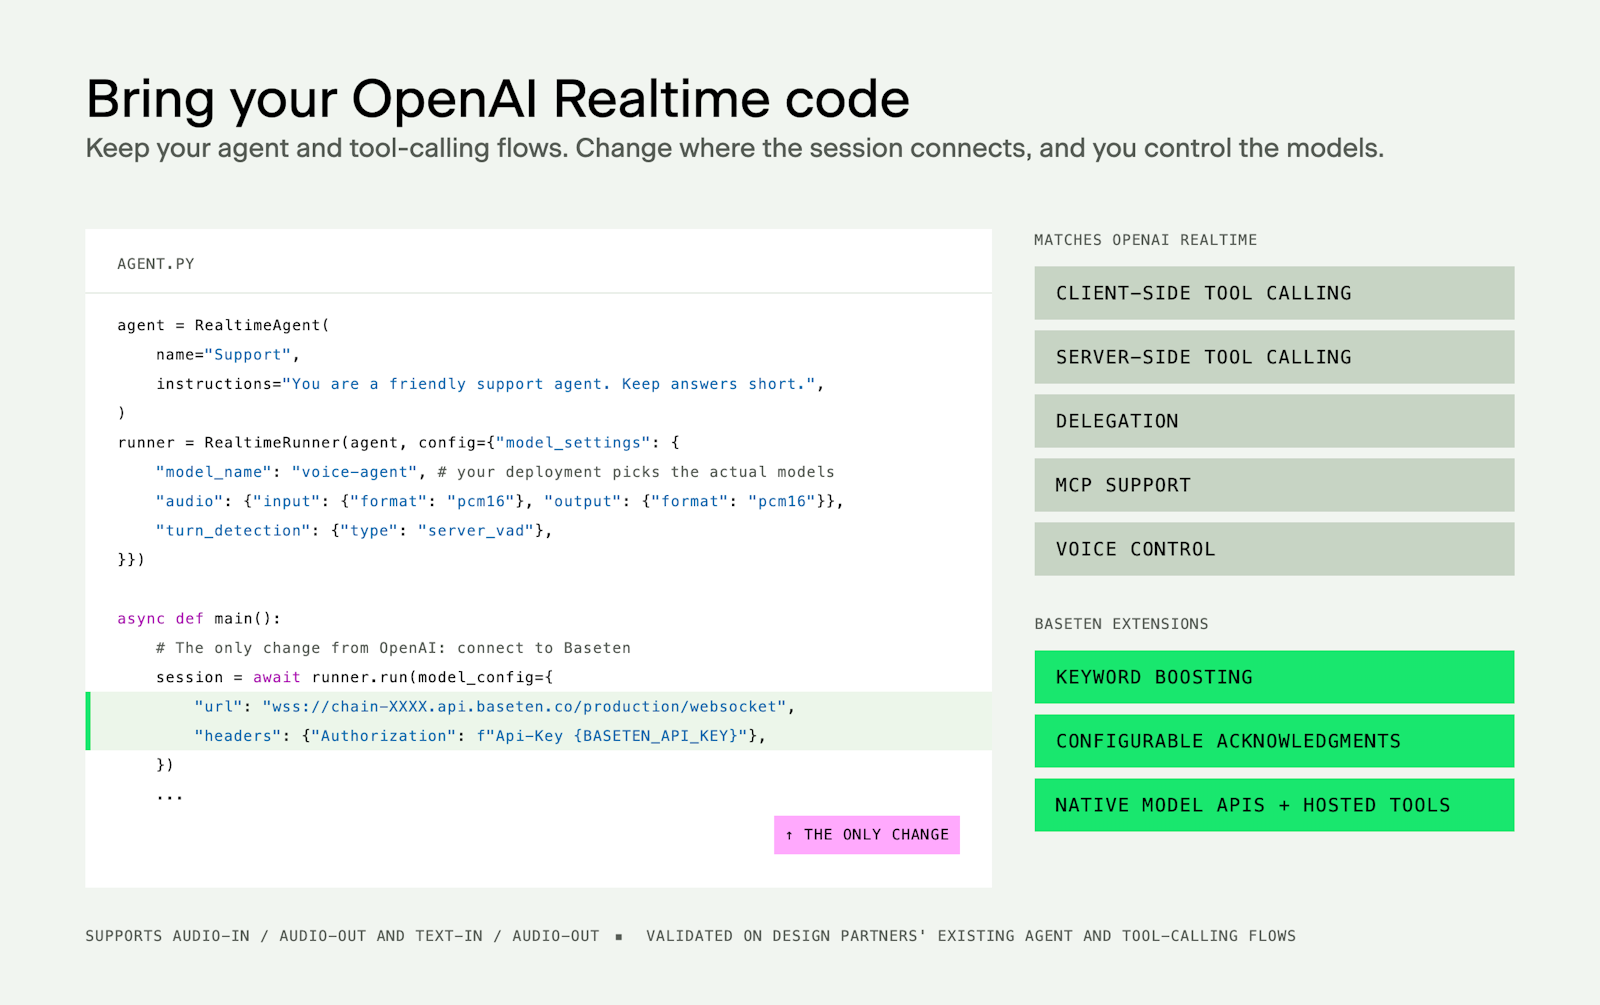
We designed the Baseten Realtime API to make migrating from a closed-source realtime API as seamless as possible. It matches the core OpenAI Realtime protocol, so workflows built on client- and server-side tool calling, delegation, MCP, and voice control move over with minimal changes, which we validated with early design partners on their existing agent flows.
Because you control the models, it also supports what many closed APIs don't: keyword boosting, configurable acknowledgments, voice cloning, and native access to our Model APIs and hosted tools. It runs in both audio-in/audio-out and text-in/audio-out modes.
Benchmarks
Latency
Our continuously optimized versions of leading open-source speech models, including Whisper, Qwen3-ASR, and Qwen3-TTS, lead third-party benchmarks in final transcript latency and time to first audio (TTFA). These per-model optimizations lower the turn-latency floor of cascaded systems, and orchestrator tuning keeps actual turn latency as close to that floor as possible.
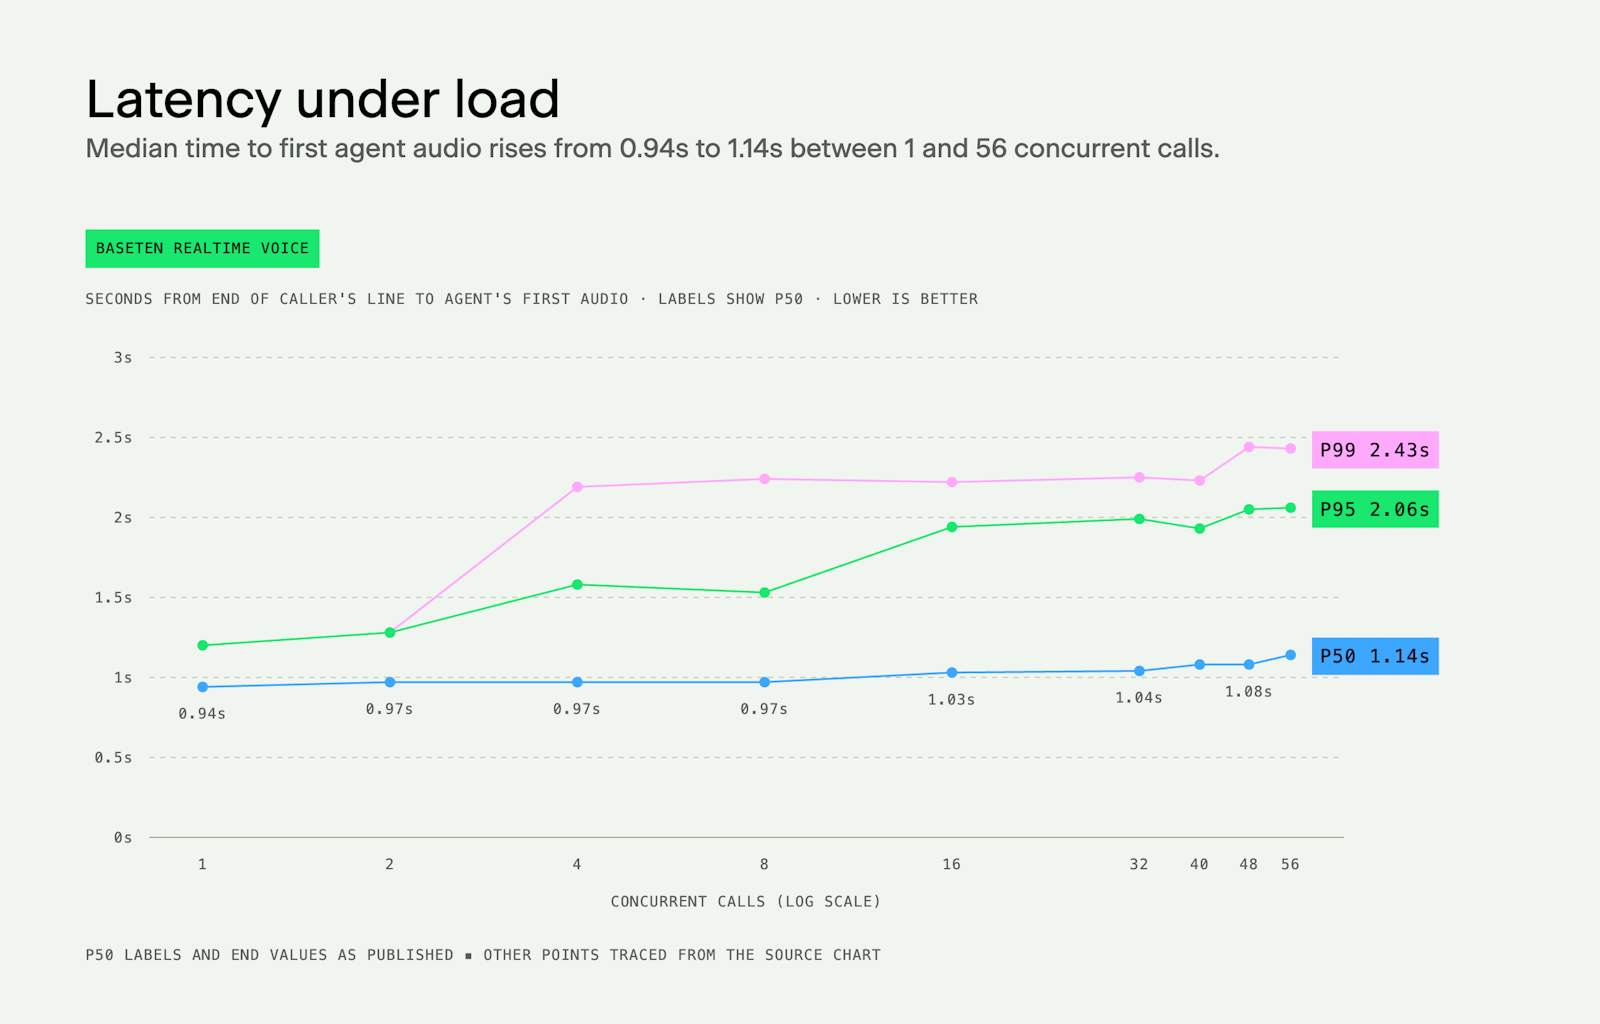
With context up to 16K tokens, median turn latency stays flat at ~1s from 1 to 56 concurrent sessions. Longer contexts can raise turn latency, so configurable context summarization can hold each session to a target context length, keeping memory bounded and performance strong at even higher concurrency.
Cost
At scale, a fully dedicated cascade is the most cost-effective way we’ve found to run voice agents, at ~$0.01 per audio minute per stream.
From 32 concurrent streams upward, cost per minute is lower than every hosted speech-to-speech API we compared. That’s because dedicated pricing further amortizes the hardware cost with each additional concurrent session. The comparison is also conservative for token-billed providers, since we omit the cached tokens they re-bill on every turn. Calls delegated to larger reasoning models are billed per token, like standard LLM endpoints.
Per-component autoscaling
With every component of the cascade running on Baseten, each one scales independently against its own concurrency target, so you can hold strict p90 and p95 latency tails. It’s also a cost lever. The STT, LLM, and TTS components of a cascade agent often saturate at different rates, so instead of scaling the whole cascade whenever one component hits its limit, capacity is scaled only for the component that needs it. This keeps GPU utilization high while lowering cost per audio minute.
Reasoning and tool-calling
Speed and cost only matter if the agent can actually complete tasks. τ²-Bench Voice measures exactly that, testing real customer support tasks over live, full-duplex phone calls.
Baseten Realtime Voice scores 73.5% on the English leaderboard split, including 93.9% on telecom, the domain with the longest tool-calling chains with delegation enabled. That makes it the leading open-source stack on the leaderboard and the highest-scoring cascaded system listed, more than doubling the cascaded baseline (31.2% pass@1). The talker-thinker setup drives this result: the co-located talker keeps turns responsive while the stronger thinker owns tool-call orchestration.
Conversational dynamics
Natural conversation depends on timing: knowing when the caller has finished and when to stay quiet. To handle this, Baseten Realtime Voice uses a joint VAD and turn detection classifier approach, built on the leading open-source solutions on TurnBench, and we’ve invested heavily in tuning it for noisy, real-world audio. On the Artificial Analysis split of Full-Duplex-Bench, which measures turn-taking and interruption handling behavior, it scores 93% (weighted), the highest among open-source full-duplex systems.
Future work
Our focus is on supporting more complex orchestration flows and making it easier to bring existing voice agent pipelines onto Baseten, where you can still utilize the above capabilities with your own orchestration logic. We’re also exploring new voice agent paradigms beyond the cascaded pipeline. These include full-duplex conversation with native speech-to-speech models, and omni models paired with dedicated TTS heads. We’ll additionally keep improving on orchestration itself - with new primitives for scheduling across the components of a cascaded pipeline.
Join the waitlist
Both the Baseten Voice Agent Stack and Baseten Realtime Voice are now in private preview, and you can sign up for our waitlist here. To learn more about supported features and the API surface, check out our documentation and recipes.
Footnotes
The Baseten Realtime Voice setup measured in this post consists of STT: Qwen3-ASR (1xRTX-6000), LLM: Gemma-4-31B (1xB200), TTS: Qwen3-TTS (1xRTX-6000) and a GLM-5.3 Fast Delegate Model on Baseten Model APIs
Task success: Artificial Analysis τ-Voice, full-duplex models (2026-11-10); GPT-Live-1 (Astra) 1 trial, GPT-Realtime-2.1 High 2 trials
Hosted cost: Artificial Analysis cost per hour of input audio (Big Bench Audio subset) ÷ 60; includes billed output and reasoning
Baseten cost: list price $18.39/hr ÷ 32 concurrent sessions, fully utilized ■ † Excl. per-token cost of GLM-5.3 Fast delegation
§ Baseten score is 73.5% pass^1 on Sierra's τ²-Bench Voice harness, self-reported; not measured by Artificial Analysis, not directly comparable