Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation


Meet bison-1 and groundhog-1, frontier American decision models
Meet bison-1 and groundhog-1: open decision models on an American backbone (Gemma 4). bison-1 is the #1-ranked decision model on Artificial Analysis.
- Published



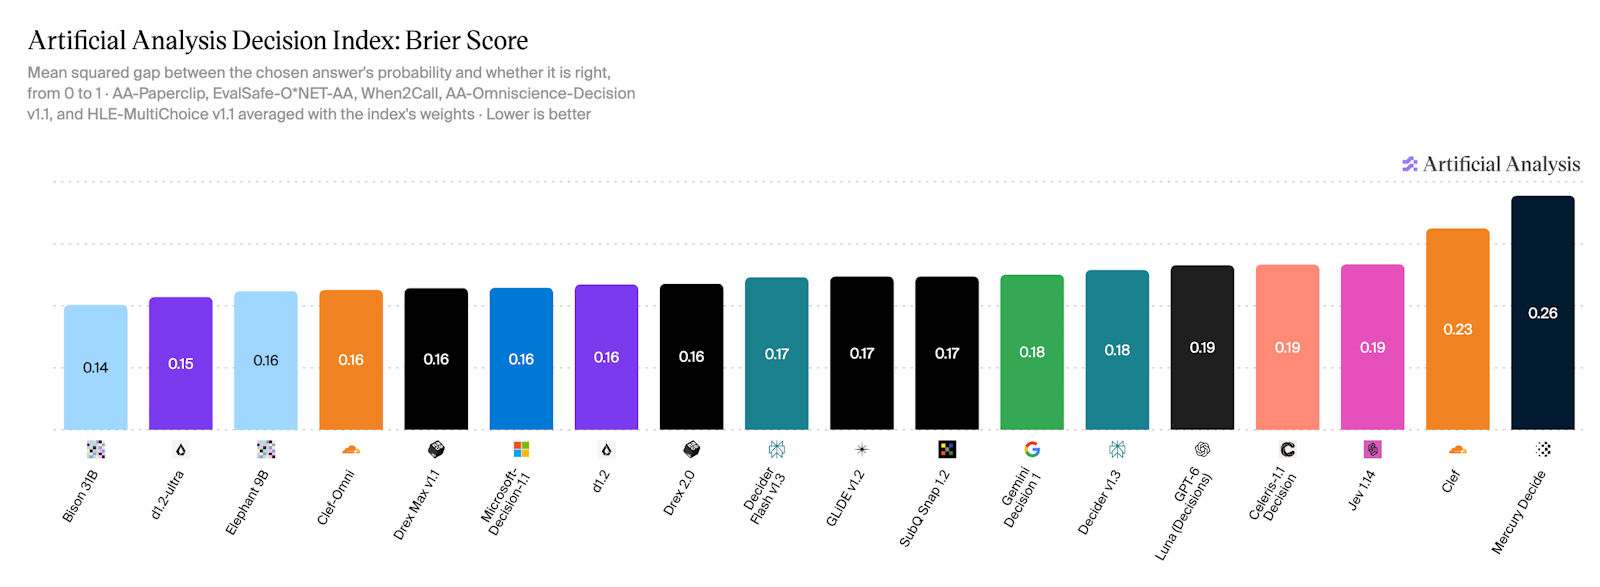
Meet bison-1 and groundhog-1, our newest decision models, built on Google’s Gemma 4 for teams that want an American base model. bison-1 is #1 of 19 decision models on the Artificial Analysis Decision Index and has the best calibration on the index. Both models offer 128k context (8x our previous models) and accept text and image input. They’re live on Baseten Model APIs with open weights on Hugging Face.
Last month, we released mammoth-1 and elephant-1, the world’s best decision models at the time. Both were built on Qwen backbones, pushed the frontier of accuracy and speed, and paved the way for us to deliver that level of performance on a Western backbone.
Supporting American companies and open models is an investment in our country’s technical strength and the ecosystem that enables more Americans to build systems they can own and adapt. We’re proud to contribute to that effort with our newest decision models, bison-1 and groundhog-1.
Built on Google’s Gemma 4, they deliver improved quality and similar speed to mammoth-1 and elephant-1, with 128k context windows and multimodal support (images and text). Both models use the same API as our existing decision models. Trying them is as simple as changing the model name.
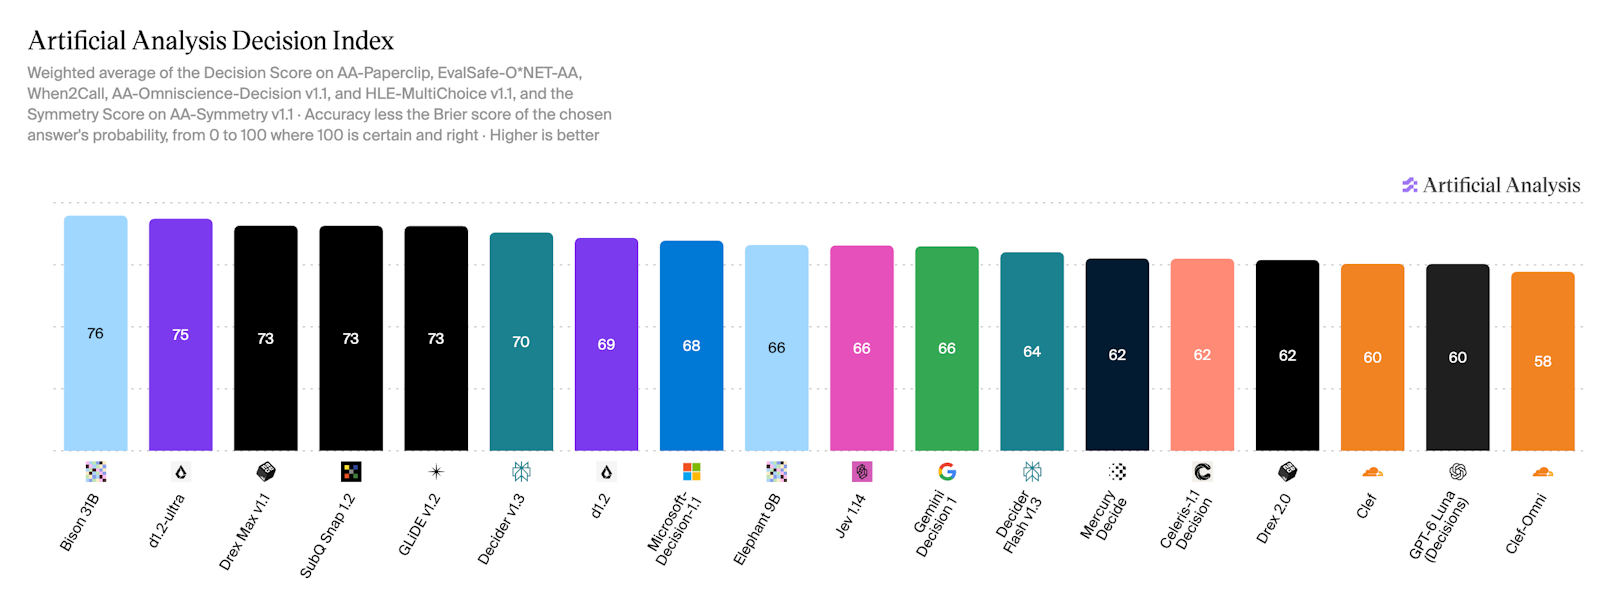
On Artificial Analysis (AA) Decision Index v2.1, bison-1 is #1 of 19 decision models with a score of 76, ahead of d1.2-ultra at 75 and mammoth-1 at 71. We expect groundhog-1 to match the performance of mammoth-1 on the official AA index.
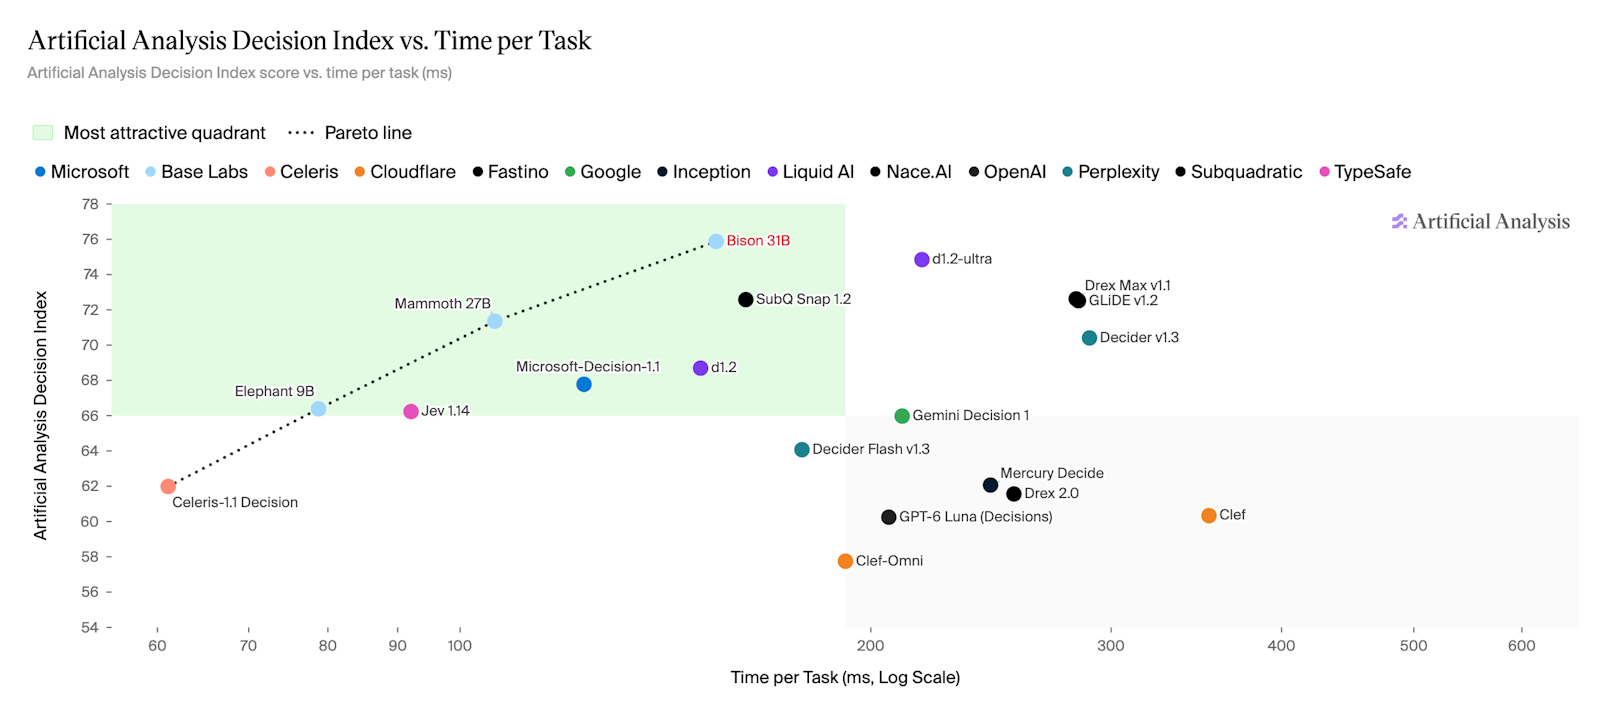
With the release of bison-1 and thanks to work from our model performance team, the Base Labs decision model family now occupies the Pareto frontier for accuracy vs time across all respective sizes from elephant-1 to bison-1.
We’ve also spent a lot of time ensuring the model is correctly calibrated. Part of this came from training on the Gemma base, but a significant gain came from scaling the use of “soft labels” in our new training data mixture. (teaching the model to be calibrated to “83% answer A, 17% answer B” rather than strictly “100% answer A”).
Every decision deserves the full picture (well, at least 128k tokens worth)
Long context matters because the detail that changes a decision may be buried far from the question. An invoice might look ready for payment, but an earlier email could show that the order was canceled. Without that history, a model could approve a payment it should reject.
bison-1 and groundhog-1 offer 8x the context available on our previous models through Model APIs, giving teams more room to include full policies or conversation histories without selecting excerpts or summarizing them first.
Good decisions start at home
We want selecting an American model to be a choice teams can make on merit, which means holding these models to the same standard as any other.
Here is where the new models fit in the family. groundhog-1 is priced like elephant-1, and bison-1 like mammoth-1, so the choice comes down to the decision at hand.
| - | bison-1 | groundhog-1 | mammoth-1 | elephant-1 | joey-1 |
|---|---|---|---|---|---|
| Parameters | 31B | 26B (MoE, ~4B active) | 27B | 9B | 2B |
| Backbone | Gemma 4 31B | Gemma 4 26B-A4B | Qwen | Qwen | Qwen3.5-2B |
| Context window on Model APIs | 128k | 128k | 16k | 16k | 16k |
| Use it when | You want the highest accuracy, with long context | You need long context at low latency and cost | Accuracy on knowledge-heavy decisions matters most | You want a stronger default at low latency | Latency or cost dominates |
| Price per 1M tokens ($) | $0.10 | $0.035 | $0.10 | $0.035 | $0.01 |
bison-1 and groundhog-1 are a starting point for more of our research on American backbones. As we improve our training data and methods, we’ll bring those advances to our growing menagerie, giving teams more reasons to choose American models on performance.
Both models (bison-1, groundhog-1) are available today on Baseten Model APIs, at $0.10 and $0.035 per million tokens. Both accept text and images and use the same API as our existing decision models. The weights are also open on Hugging Face: bison-1 and groundhog-1. Keep an eye out for more models to come!